Skip to content

2006

Spam zombies -- we need to cure the disease, not suppress the symptoms

Here's a great presentation from Joe St Sauver presented at the London Action Plan meeting recently: Infected PCs Acting As Spam Zombies: We Need to Cure the Disease, Not Just Suppress the Symptoms

Some key points in brief:

Despite all our ongoing efforts: the spam problem continues to worsen, with nine out of every ten emails now spam; spam volume has increased by 80% over just the past few months and users face a constantly morphing flood of malware trying to take over their computers. Bottom line: we're losing the war on spam.

The root cause of today's spam problems is spam zombies, with 85% of all spam being delivered via spam zombies.

The spam zombie problem grows worse every day (with over ninety one million new spam zombies per year)

Users don't, won't, or can't clean up their infected PCs; and ISPs can't be expected to clean up their infected customers' PCs.

Filtering port 25 and doing rate limiting is like giving cough syrup to someone with lung cancer -- it may suppress some overt symptoms but it doesn't cure the underlying disease.

Filtered and rate-limited spam zombies CAN still be used for many, many OTHER bad things, and they represent a huge problem if left to languish in a live infected state.

Joe's take -- "we're in the middle of a worldwide cyber crisis". I agree. He suggests a new strategy:

It is common for universities to produce and distribute a one-click clean-up-and-secure CD for use by their students and faculty. It's now time for our governments to produce and distribute an equivalent disk for everyone to use.

I agree the existing schemes are clearly not working; this is an interesting suggestion. Read/listen to the presentation in full for more details; pick up PDF, PPT and video here.

anti-spam botnets ddos internet joe-st-sauver london-action-plan security smtp windows zombies

Massive spam volumes causing ISP delays

Via Steve Champeon's daily links, the following spam-in-the-news stories illustrate a rising trend:

Huge amounts of spam are said to be responsible for delays in the email network of NZ ISP Xtra.

Several customers have vented their frustrations on an Xtra website message board saying some emails were days late, The New Zealand Herald reports.

... Record volumes of spam meant such problems would be "an unfortunate and on-going reality of the internet not specific to any provider", he said.

Mr Bowler said Telecom had invested "tens of millions of dollars" in email and anti-spam software and worked closely with two of the world's leading anti-spam vendors.

Holiday spam e-mails are to blame for slowing message delivery to faculty and staff in schools across Kentucky ...

"Some 123-reg customers may have experienced intermittent delays in their emails in the last two weeks. We had received a particularly high level of image-based spam attacks over a short period of time," the Pipex subsidiary said.

Small businesses are threatening legal action over continuing glitches with Xtra's email service and the Consumers' Institute says they may have a case.

Several people have contacted the Herald complaining that delays and non-deliveries of emails over the past three weeks on the Xtra network are severely affecting their businesses. ...

The institute's David Russell said home users could claim compensation for email delays if they had suffered "a real measurable loss".

Non-commercial customers were covered by the Consumer Guarantees Act and services they paid for had to be of a "reasonable quality".

Although it might be more difficult for small business owners, they could also have a case, Mr Russell said. "If there has been a considerable amount of money, they could consider legal action or, if the amount was smaller, they could go through the disputes tribunal."

In other words, the DDOS-like elements of the spam problem are becoming an increasing worry; even with working spam filtering in place, the record size of zombie botnets means that spammers can now destroy organisations' computing infrastructure, almost accidentally.

Spammers don't care if an organisation's infrastructure collapses while they're sending their spam to it -- they just want to maximise exposure of their spam, by any means necessary. If that requires knocking a company off the air entirely for a while, so be it.

I'm not sure what can be done about this, in terms of filtering. It may finally be time to fall back to a "side channel" of trusted, authenticated SMTP peers, and leave the spam-filled world of random email from people and organisations you don't know to one side, as a lower-priority system which can (and will, frequently) collapse, without affecting the 'important' stuff. What a mess. :(

Alternatively, maybe it's time for governments to start putting serious money into botnet-spam-related arrests and prosecution.

This has additional issues for ISPs, too, btw -- I wonder if Earthlink are taking note of that Xtra lawsuit story above....

anti-spam botnets ddos delays filtering security spam

Cliche-finder bookmarklet

Quinn posted a link to a nifty CGI by Aaron Swartz which detects uses of common cliches, with the list of cliches to avoid taken from the Associated Press Guide to News Writing. In addition, she also mentioned there's the Passivator, 'a passive verb and adverb flagger for Mozilla-derived browsers, Safari, and Opera 7.5'.

Combining the two, I've hacked together a bookmarklet version of the cliche finder -- it can be found on this page. (Couldn't place it inline into this post due to stupid over-aggressive Markdown, grr.)

Fun! Probably not IE-compatible, though.

bookmarklets cliches english grammar hacks javascript writing

5 things

Tagged by richi! drat. OK, here are 5 things you probably don't know about me:

  1. I'm a certified SCUBA diver, at PADI Advanced Open Water Diver level. (oh, look, so's Tom Raftery!)

  2. I generally try to avoid meeting my heroes, since I get quite tongue-tied in the presence of people I admire -- I once stammered "I think you're brilliant" at Alex Paterson, instead of anything more witty or interesting.

  3. I met my wife at a student occupation in university, where her knowledge of the science and nature questions in Trivial Pursuit, and amazing looks of course, got me hooked ;)

  4. I could listen to Brian Eno's Taking Tiger Mountain By Strategy and Here Come The Warm Jets on repeat for several weeks, if necessary.

  5. I was a child model, modelling (among other things) underpants for Dunnes Stores! It's all been downhill since then, really ;)

Passing it on: go for it, Brendan, Colm, Lisey, and Jason.

5things blog-tags five-things life memes richi

An anti-challenge-response Xmas linkfest

As all right-thinking people know by now, Challenge-response spam filtering is broken and abusive, since it simply shifts the work of filtering spam out of your email, onto innocent third-parties -- either your legitimate correspondents, people on mailing lists you read, or even random people you have never heard of (due to spam blowback).

I've ranted about this in the past, but I'm not alone in this opinion -- and frequently find myself explaining it. To avoid repeating myself, here's a canonical collection of postings from around the web on this topic.

Description: This "selfish" method of spam filtering replies to all email with a "challenge" - a message only a living person can (theoretically) respond to. There are several problems with this method which have been well known for many years.

  1. Does not scale: If everyone used this method, nobody would ever get any mail.
  2. Annoying: Many users refuse to reply to the challenge emails, don't know what they are or don't trust them.
  3. Ineffective: Because of confusion about these emails, many of them are confirmed by people who did not trigger them. This results in the original malicious email being delivered.
  4. Selfish: This is the problem we are mainly concerned with. By using challenge/response filtering, you are asking innumerable third parties to receive your challenge emails just so that a relatively few legitimate ones get through to the intended recipient.

C-R systems in practice achieve an unacceptably high false-positive rate (non-spam treated as spam), and may in fact be highly susceptible to false-negatives (spam treated as non-spam) via spoofing.

Effective spam management tools should place the burden either on the spammer, or, at the very least, on the person receiving the benefits of the filtering (the mail recipient). Instead, challenge-response puts the burden on, at best, a person not directly benefitting, and quite likely (read on) a completely innocent party. The one party who should be inconvenienced by spam consequences ¿ the spammer ¿ isn't affected at all.

Worse: C-R may place the burden on third parties either inadvertantly (via spoofed sender spam or virus mail), or deliberately (see Joe Job, below). Such intrusions may even result in subversion of the C-R system out of annoyance. Many recent e-mail viruses spoof the e-mail sender, including Klez, Sobig variants, and others.

The collateral damage from widely used C/R systems, even with implementations that avoid the stupid bugs, will destroy usable e-mail. [jm: in fairness, this was written in 2003.]

Challenge systems have effects a lot like spam. In both cases, if only a few people use them they're annoying because they unfairly offload the perpetrator's costs on other people, but in small quantities it's not a big hassle to deal with. As the amount of each goes up, the hassle factor rapidly escalates and it becomes harder and harder for everyone else to use e-mail at all.

I'm skeptical of CR as a response to email. If you're the first on your block to adopt CR, and if nobody else uses anti-spam technology, then CR might provide you some modest benefit. But it¿s hard to see how CR can be widely successful in a world where most people use some kind of spam defense.

If these systems are so brain-dead as to not bother adding my address to the whitelist when the user sends me e-mail, I have serious trouble understanding why anyone is using them.

Is it just me? Is this too hard to figure out?

Anyway, there's another 5 minutes I'll never get back. It's too bad there's no mail header to warn me that "this message is from a TDMA user", because then I'd be able to procmail 'em right to /dev/null where they belong.

Ugh.

This bullshit is not going to "solve" the spam problem, people. If that's your solution, please let me opt out. Forever.

C/R slows down and impedes communication by placing unwanted barriers between you and your clients/suppliers.

If you must insist on using some form of C/R please make sure that you whitelist my address before you contact me as I will not reply to challenges.

We will not answer any challenges generated in response to our mailing list postings. Thus, if you're using a challenge-response system and not receiving TidBITS, you'll need to figure that out on your own. Also, if you send us a personal note and we receive a challenge to our reply, we may or may not respond to it, depending on our workload at the time.

uol.com.br uses a very broken method of anti-spam. Everytime someone sends an email message to one of their members, they send back a verification message, asking the original sender to click a link before they will allow the message through. These messages are themselves a form of spam, and the resulting back-scatter of these messages is altogether bad for the Internet, the UOL member, and all of the UOL member's contacts. UOL is aware of the complaints against them, and they refuse to correct the issue, claiming that their members love the service.

I hate C/R systems. With a passion. I absolutely will not respond to them. They go in the trash. I don't get them very often but I get them more and more. I think they have the potential to seriously damage email communication as we know it. And I'm not alone in this opinion.

Phew.

abuse anti-spam backscatter blowback bounces c-r challenge-response email filtering rants smtp

Linux USB frequent reconnects - workaround

I've been running into problems recently (since several months ago at least), with USB hardware on my Thinkpad T40 running Ubuntu Hoary Dapper; in particular, every time I plug in my iPod or one of my USB hard disks nowadays, I get this:

[5008549.187000] usb 4-3: USB disconnect, address 14
[5008550.143000] usb 4-3: new high speed USB device using ehci_hcd and address 18
[5008552.643000] usb 4-3: new high speed USB device using ehci_hcd and address 27
[5008557.393000] usb 4-3: new high speed USB device using ehci_hcd and address 43
[5008557.893000] usb 4-3: new high speed USB device using ehci_hcd and address 44
[5008558.643000] usb 4-3: new high speed USB device using ehci_hcd and address 46
[5008558.895000] ehci_hcd 0000:00:1d.7: port 3 reset error -110
[5008558.896000] hub 4-0:1.0: hub_port_status failed (err = -32)
[5008559.893000] usb 4-3: new high speed USB device using ehci_hcd and address 48
[5008562.643000] usb 4-3: new high speed USB device using ehci_hcd and address 58
[5008563.143000] usb 4-3: new high speed USB device using ehci_hcd and address 59
[5008563.643000] usb 4-3: new high speed USB device using ehci_hcd and address 60
[5008570.143000] usb 4-3: new high speed USB device using ehci_hcd and address 85

This repeats ad infinitum until the USB device is disconnected.

I had this down as a hardware issue (since it started happening just after warranty expiration ;), but some accidental googling revealed several other cases -- and a workaround:

sudo modprobe -r ehci-hcd

Run that repeatedly, each time replugging the device and monitoring dmesg via watch -n 1 'dmesg | tail' in a window, until the device is finally recognised as a USB hard disk. It generally seems to take 3 or 4 attempts, in my experience.

This LKML thread suggests hardware changes can cause it, but this hardware hasn't changed in years. Annoying.

Anyway, this is ongoing. This tip seems to help, but it might be just treating a symptom, I don't know -- just posting for google and posterity... and to moan, of course :(

bugs disks ehci-hcd hardware ipod linux storage usb

Threadless deals with plagiarism

(Updated since original posting; see end of post for details)

Paging boogah!

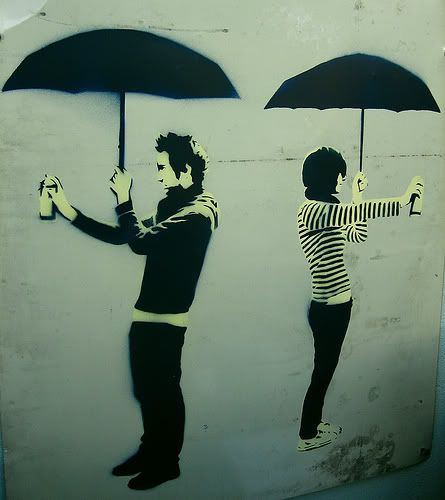
Interesting situation playing out at Threadless -- I think this may be the first time a stolen design made it through voting and so on, onto cotton, without being spotted. Here's the design, supposedly by someone called 'rocketrobyn':

And here's the (apparently original) stencil art by miso and ghostpatrol:

BTW, note the perspective being copied from the photo's odd angle, to the shirt design...

The Threadless design's submission page has some classic comments:

  • Boney_King_of_Nowhere: Wow. Are you by any chance a fan of Bansky? Because this is almost a rip off. Almost. Awsome though.
  • rocketrobyn (this is my design): Thank you for the positive comments. I really like this shirt too! [...] I'm not sure who Bansky [jm:sic] is, but I'll check it out!

Heh.

I heard about this via You Thought We Wouldn't Notice, a street-design plagiarism blog, where ghostpatrol (one of the stencil artists) posted a blog post about the situation. In the comments there, Jake from Threadless pipes up:

jake n on 12 Dec 2006 at 4:30 am

hey, jake here from threadless. i was just made aware of this situation and want to give you all my assurance that we will handle this properly.

the designer will not be paid and the design will either be removed or licensed from the original designer if they are willing.

give us a couple days to sort the details.

Not to appear whingy, 2 hours later "n." posts:

The original owners are not willing to license this design to Threadless, and want it removed from the site. Neither artist has yet been contacted by Threadless.

Bit of patience there ;)

More links:

It's an interesting situation, and so far Threadless is handling it very well as far as I can see -- the only people who aren't are some other graf and stencil artists in the reaction threads, vituperating about Threadless not using psychic powers to detect plagiarism:

i tell you, you aren't printing any of my subs, i know it as they score way too low to get noticed. but on the off chance that someone rips off a design i've done, as blatantly as this...i would definitely seek reparations from threadless and the offending subber. do a background check with the subbers available websites etc.

Background checks?! wtf.

Good reaction from miso though:

Once again, we own automatic copyright on these images,...

To clarify -- we are not blaming Threadless. They didn't take the design knowing that it was stolen [if they had done so witch such knowledge, we would be approaching this very differently].

This is the fault of the "designer", and hopefully this will sort itself out in the next few days. [Who, by the way, has claimed to have done these designs -- "This is a t-shirt I designed for Threadless."]

As yet, either GP nor I have yet been contacted by either the company or "designer" to fix this, but Jake from Threadless has left a very nice comment for us on "You Thought We Wouldn't Notice".

The Threadless blog reactions are worth watching if you want to follow the ongoing drama.

Update: reposted to preshrunk. In the comments there, someone notes that it's not the first Threadless tee to make it to production before plagiarism was spotted -- The Killing Tree was first. There are some oblique references to this in this blog post's comments.

apparel clothing copyright graffiti ip plagiarism stencils tee-shirts threadless

Backscatter in InformationWeek

Yay! Kudos to Richi Jennings, who's been trumpeting the dangers of backscatter to InformationWeek recently. It's a great article. I particularly like how it digs up this impressively off-the-mark quote:

Tal Golan, CTO, president, and founder of Sendio, maker of a challenge/response e-mail appliance used by more than 150 enterprise consumers, disagrees strongly with Jennings's assertion that challenge-based filtering has problems. "Without question, the benefit to the whole community at large drastically outweighs that FUD [fear, uncertainty, and doubt] that's out there in the marketplace that somehow challenge/response makes the problem worse," he says. "The real issue is that filters don't work. From our perspective, challenge/response is the only solution. This whole concept of backscatter is just not true. Very, very rarely do spammers forge the e-mail addresses of legitimate companies anymore."

hahahaha. Well, since last Thursday, "very very rarely" translates as "214 MB of backscatter in my inbox". The facts aren't on Tal Golan's side here...

(PS: SpamAssassin 3.2.0 will include backscatter detection.)

anti-spam backscatter bounces challenge-response filtering funny richi-jennings sendio spam

An Post: 75% lost-parcels rate so far

I don't know what's going on with An Post, the Irish postal service, these days -- I've been having some pretty bad luck with them.

For my birthday, I was lucky enough to be given a Thingamagoop -- it took a while (hey, they're hand-made) but was shipped on Nov 7th from the US. Bleep Labs accidentally shipped me two, apparently, but only one has arrived -- on Nov 16th, 9 days after shipping. The other one's still AWOL nearly a month later.

I then ordered something from Sendit.com on Nov 17th, as a birthday gift for Nov 30th. It was shipped from their Belfast offices on Nov 18th, and still hasn't arrived to date. Sendit were champs, however, and refunded the purchase as soon as I rang them on the 30th (I'd recommend their services, no problem).

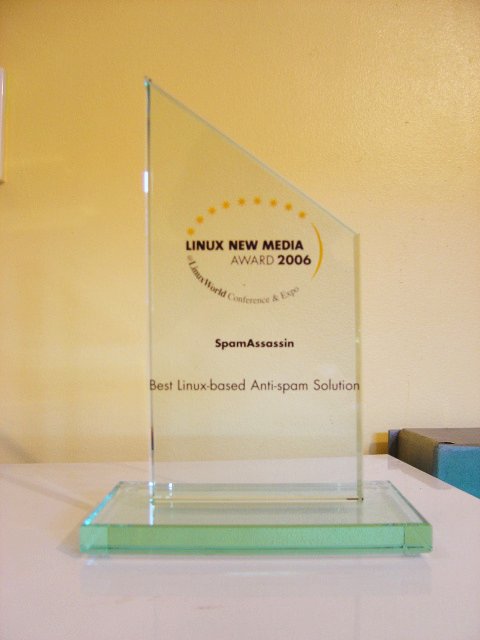
Finally, SpamAssassin was lucky enough to win a Linux New Media Award 2006 for 'Best Linux-based Anti-spam Solution' -- nifty! As part of this, a (physical) trophy is apparently winging its way from Germany, and was apparently shipped on November 27th. Guess what: no sign.

In other words, in the past month, 75% of the parcels sent to me seem to have gone AWOL. All I can do is hope that they've just been delayed, rather than suffer a worse fate. In particular, I hope that trophy turns up -- it's the only physical award we've ever received :(

Can anyone think of a good avenue to track these down? The website seems pretty negative, and what I've heard seems to be along the lines of 'turn up at the sorting depot, cross your fingers, and see if they've been misdelivered'. Ick.

an-post dublin ireland post

SpamAssassin as an EC2 service

I had a bit of an epiphany while chatting to Antoin about the qpsmtpd/EC2 idea. Craig had the same thoughts.

Here's the thing -- there's actually no need to offload the SMTP part at all. That stuff is tricky, since you've got to build in a lot of fault tolerance, quality-of-service, uptime, etc. to ensure that the MX really is reachable. Since an EC2 instance will lose its "disks" once rebooted/shut down, you need to store your queues in Amazon S3 -- which has differing filesystem semantics from good old POSIX -- so things get quite a bit hairier. On top of that, it requires a little RFC-breakage; there are issues with using CNAMEs in MX records, reportedly.

However, if we offload just the spamd part, it becomes a whole lot simpler. The SPAMD protocol will work fine across long distances, securely, with SSL encryption active, and SpamAssassin will work fine as a filtering system in an entirely stateless mode, with no persistent-across-reboots storage. (What about the persistent-storage aspects of spamd operation? There's just the auto-whitelist, which can be easily ignored, and I haven't trained a Bayes database in 2 years, so I doubt I'll need that either ;)

If the spamd server is down or uncontactable, spamc will handle this and retry with another server, or eventually give up and pass the message through, safely intact (though unscanned).

Given that there's a cool third-party ClamAV plugin now available for SpamAssassin, this system can offload the virus-scanning work, too.

So here's the new plan: run the MTA, MX, and the super-lean "spamc" client on the normal MX machine -- and offload the "spamd" work to one or more EC2 machines.

Basically, there would be a CNAME record in DNS, listing the dynamic DNS names of the EC2 spamd instances. Then, spamc is set to point at that CNAME as the spamd host to use. As EC2 instances are started/removed, they are added/removed from that CNAME list and spamc will automatically keep up.

Pricing is reasonably affordable -- don't send over-large messages to the EC2 spamd; rate-limit total incoming SMTP traffic in the MTA; and use the SPAMD protocol's REPORT verb to reduce the bandwidth consumption of mails in transit by ensuring that the mail messages are only transmitted one-way, MX-to-EC2, instead of both MX-to-EC2 and EC2-to-MX. That will keep the bandwidth pricing down.

Recent figures indicate that I got about 90MB of mail per day, at peak, over the past weekend (which nearly DOS'd my server and caused some firefighting) -- 68MB of spam, and 13MB of blowback. At 20 cents per GB, that's 1.8 cents per day for traffic. Plus the $0.10 per instance hour, that's $2.42 per day to run a single EC2 instance to handle DDOS spikes. Of course, that can be shut down when load is low.

Yep, this is looking very promising. Now when are Amazon going to let me onto the beta program for EC2?...

amazon aws ec2 spamassassin spamc spamd

Using qpsmtpd and Amazon EC2 to provide SMTP-DDoS protection

Like a few other anti-spammers, I found myself under a hitherto-unprecedented level of spam blowback this weekend. Disappointingly, there are still thousands of SMTP servers configured to send bounce messages in response to spam.

Even with the anti-bounce ruleset for SpamAssassin, the volume was so great that our creaky old server had a lot of difficulty keeping up -- once the messages got to SpamAssassin, the load issues had already been created. Also, Postfix's anti-spam features really weren't designed to deal with blowback.

While attempting to take some shortcuts in the setup on our server to deal with this, a great idea occurred to me -- why not come up with an app that uses Amazon EC2 to flexibly provision enough server power and bandwidth to pre-filter the SMTP traffic for an MX under attack?

I'm basically thinking of qpsmtpd, with SpamAssassin and/or other antispam blobs active, running in an Amazon EC2 server image. Multiple images can be brought up, and added to the attacked domain's MX record at an equal priority, to take load off the main (overloaded) MX.

Now to cogitate a little -- details to follow...

amazon anti-spam aws ec2 qpsmtpd s3 smtp

Working out electricity costs for your appliances and hardware

This question came up on a forum I'm on. It turns out it's really quite easy to work out -- this page covers pretty much all the details.

In addition to what's there, it's worth noting that the current Irish price for a kilowatt-hour under the ESB's domestic rate is 12.73 cents per kWh, which works out as 14.41 cents per kWh once the 13.5% VAT is added in. So Irish users, pretend you live in New Hampshire (15 cents per kWh) to get realistic figures from the excellent cost calculator.

Using this, it looks like if I was to leave an 160W desktop computer on permanently in Ireland, I'd be spending 215 euros per year to power it. Wow, that's pricey! My strategy of using low-noise, low-power hardware for home servers has paid off already, in that case. ;)

For what it's worth, if you're worrying about the power consumption of an NTL digital Pace Digital TV set-top box -- if this Pace presentation is anything to go by, it appears the standby power consumption is on the order of 1-2 watts -- about 2 euros per year. Grand.

costs electricity environment green money power saving watts

Labour's flat-rate bus tickets

Well, that was quick!

Right after posting this, I hear about Labour's new transport strategy for Dublin. Here's the top 3 items:

  • Labour will increase the Dublin Bus fleet by 50% (500 buses), significantly increasing frequency and reducing waiting times.

  • Will complete the Quality Bus Corridors, and greatly reduce journey times.

  • Will introduce a EUR 1 per-trip fare for adults and a 50c per-trip fare for children.

The flat-rate fee structure makes a lot more sense than the confusing and rip-off-ish current model, whereby if you don't know in advance how much a particular journey is going to cost, you're given a useless receipt instead of change. This wierd and rip-off-ish policy has certainly stopped me from catching buses in the past. In general, flat-rate pricing models appear to encourage use in other fields. And the increase in the fleet is obviously a fantastic idea. Fantastic stuff!

Read the full policy paper here (as a PDF).

dublin ireland labour politics public-transport

Dublin transport survey

Via Lean comes this, I think from the Irish Times:

One-half of Dublin drivers would never use bus - survey

One-half of all car drivers in the greater Dublin area say they would not switch to travelling by bus, even if services were improved, according to a new survey.

Unreliability, long waiting times and poor connections were cited as the main reasons for not taking the bus in the survey carried out for the Dublin Transportation Office (DTO).

As many as four out of five people expressed dissatisfaction with traffic congestion and access to the Luas.

Just over 35 per cent of those surveyed were satisfied with the quality and upkeep of roads, and with facilities for cycling. Over one-half said they were happy with the reliability, frequency and cost of buses.

Almost 2,500 people were interviewed for the survey and a similar number of travel diaries were compiled. The car is the main form of transport in the region, used by 45 per cent of respondents. Some 18 per cent relied on the bus and 16 per cent said walking was their main form of transport. Just 2 per cent used the Luas more often than other modes of transport, and 3 per cent used the DART or local train. Two per cent cycled and 1 per cent relied on taxis.

Of those who said they might switch to the bus, over 60 per cent said more frequent services was the main change needed. Accurate timetables and stops closer to destinations were also called for.

Respondents linked transport by car to comfort, convenience and reliability. In contrast, buses were viewed as being for older people and people with no other choice. Bus transport was favourably viewed for going out socially and for being reasonably priced.

The Luas was seen as modern, while DART and train services were viewed as fast and safe. Cycling and walking were viewed as healthy and environmentally friendly, but for young people.

Great figures -- they sound pretty accurate.

The novelty of being home in a (relatively) bike- and public-transport-friendly city has worn off for me by now -- I'm now more familiar with buses that aren't a dumping ground for the homeless and mentally ill, and that do actually tend to pass both your origin and destination in a single journey. But that was in Orange County, possibly one of the most public-transit-hostile societies in the developed world, and compared to a more sane standard, Dublin still has a major problem.

By the way, it's interesting to note Ireland's move OC-wards on many fronts. When I got back, I was shocked to see tubby children being driven to school by mobile-phone-wielding, SUV-driving parents -- the very worst aspects of US suburban-sprawl life being happily parrotted over here. :(

cities cycling dublin life public-transport

Spam filter evasion self-defeating?

Donncha asks, is spam self-defeating?

has anyone else noticed that the new generation of gif based stock-trading spams are getting really hard to read? In the last one I had to squint and look really carefully to find out what stock was hot and a sure-buy today!

I've been wondering about this, too. We continually push spammers further and further from comprehensibility, since comprehensible spam is easily-filtered spam, but the spam flood doesn't stop. In fact, spam volumes have shot up higher than ever.

My theory is that it's a symptom of the spam side of things being a market in itself (and an inefficient, scam-heavy one at that).

IMO, the people providing the underlying products advertised in "high-end" spam -- the pill-peddlers and stock pumpers -- no longer control the technical details of how or where the spam is sent. Instead, they are the customers of professional spam gangs who do that, and take care of the obfuscation, filter-evasion, etc.

In other words, the pill-peddlers and scam operators are getting ripped off, too. They think their products or scams will be advertised in a comprehensible manner, in readable emails; but instead, odd, opaque 3-word messages with "cut and paste this" lines, hidden inside filter-evasion text and bits of Project Gutenberg, are what gets delivered to the victims.

I can't imagine the clickthrough rates are exactly stellar on that. So I'd guess the spammers are responding by pushing up volumes to attempt to increase clickthrough/sales volumes. Wonder if it's working or not?

anti-spam filtering obfuscation spam

Planet Antispam Update

Hey, some Planet Antispam updates. I've upgraded to Planet 2.0, and that seems to have solved some of the wierdness with consuming Atom feeds.

Also, there are two new antispam weblogs added to the subscription list:

Welcome guys!

(btw, if you're wondering what happened to the music post -- I moved it over here, to the mp3 blog where it was supposed to be posted in the first place, duh ;)

aggregation antispam planet planet-antispam weblogs

The nightmare that is Ryanair

It's interesting reading US weblogs when they wax enthusiastic about Ryanair, typically on the foot of this BusinessWeek article.

Here's the thing -- flying Ryanair is a deeply unpleasant experience. I've heard rumour that their staff are paid commission based on how many discretionary charges they can pile onto the basic fare -- leaving you feeling nickled and dimed at every turn -- and that certainly matches with my experience. I mean, I've had better service in train stations in Uttar Pradesh.

In our case, our "no more" moment was after a trip to Spain earlier this year, where we were humiliated for attempting to shift around luggage instead of immediately paying the charges liable once you exceed 15 kilos (33 pounds). (Naturally, there's no weighing scales until you get right in front of the check-in desk...) Once it became clear we didn't want to pay the fee, the check-in person screamed at us, and sent us to the back of the check-in queue -- like bold schoolchildren!

This level of service is pretty standard, going by local word of mouth. Several of my friends have, like me, vowed never to fly them again, even picking more expensive flights to more distant airports to avoid it.

It's certainly not comparable to JetBlue, or any other low-fare airline I've had the pleasure of dealing with -- this is a level below. The BusinessWeek article ends with:

American long-haul discounters aren't likely to go to the extremes Ryanair has gone to sell basic services, but they're paying more attention to Ryanair these days. "They're on the cutting edge," says Tad Hutcheson, vice-president for marketing at AirTran, which recently assigned two marketing staffers to spend a week flying on Ryanair. "Charging for Cokes or snacks, blankets or pillows--I'm not sure Americans are ready for that."

Well, I certainly hope not, for their sakes!

business cluetrain ryanair service travel

Bleadperl regexp optimization vs SA

I've been looking some more into recent new features added to bleadperl by demerphq, such as Aho-Corasick trie matching, and how we can effectively support this in SpamAssassin. Here's the state of play.

These are the "base strings" extracted from the SpamAssassin SVN trunk body ruleset (ignore the odd mangled UTF-8 char in here, it's suffering from cut-and-paste breakage). A "base string" is a simplified subset of the regular expression; specifically, these are the cases where the "base strings" of the rule are simpler than the full perl regular expression language, and therefore amenable to fast parallel string matching algorithms.

The base strings appear in that file as "r" lines, like so:

r I am currently out of the office:__BOUNCE_OOO_3 __DOS_COMING_TO_YOUR_PLACE
r I drive a:__DOS_I_DRIVE_A
r I might be c:__DOS_COMING_TO_YOUR_PLACE
r I might c:__DOS_COMING_TO_YOUR_PLACE

The base string is the part after "r" and before the ":"; after that, the rule names appear.

Now, here are some limitations that make this less easy:

  • One string to many rules: each one of those strings corresponds to one or more SpamAssassin rules.

  • One rule to many strings: each rule may correspond to one or more of those strings. So it's not a one-to-one correspondence either way.

  • No anchors: the strings may match anywhere inside the line, similar to ("foo bar baz" =~ /bar/).

  • Multiple rules can fire on the same line: each line can cause multiple rules to fire on different parts of its text.

  • Subsumption is not permitted: the base-string extractor plugin has already established cases where subsumption takes place. Each string will not subsume another string; so a match of the string "food" against the strings "food" and "foo" should just fire on "food", not on "foo".

  • Overlapping is permitted: on the other hand, overlapping is fine; "foobar" matched against "foo" and "oobar" should fire on both base strings. (The above two are basically for re2c compatibility. This is the main reason the strings are so simple, with no RE metachars -- so that this is possible, since re2c is limited in this way.)

  • Most rules are more complex: most of the ruleset -- as you can see from the 'orig' lines in that file -- are more complex than the base string alone. So this means that a base string match often needs to be followed by a "verification" match using the full regexp.

Now, the problem is to iterate through each line of the (base64-decoded, encoding-decoded, HTML-decoded, whitespace-simplified) "body text" of a mail message, with each paragraph appearing as a single "line", and run all those base strings in parallel, identifying the rule names that then need to be run.

This is turning out to be quite tricky with the bleadperl trie code.

For example, if we have 3 base strings, as follows:

  hello:RULE_HELLO
  hi:RULE_HI
  foo:RULE_FOO

At first, it appears that we could use the pattern itself as a key into a lookup table to determine the pattern that fired:

  %base_to_rulename_lookup = (
    'hello' => ['RULE_HELLO'],
    'hi' => ['RULE_HI'],
    'foo' => ['RULE_FOO']
  );

  if ($line =~ m{(hello|hi|foo)}) {
    $rule_fired = $base_to_rulename_lookup{$1};
  }

However, that will fail in the face of the string "hi foo!", since only one of the bases will be returned as $1, whereas we want to know about both "RULE_HI" and "RULE_FOO".

m//gc might help:

  %base_to_rulename_lookup = (
    'hello' => ['RULE_HELLO'],
    'hi' => ['RULE_HI'],
    'foo' => ['RULE_FOO']
  );

  while ($line =~ m{(hello|hi|foo)}gc) {
    $rule_fired = $base_to_rulename_lookup{$1};
  }

That works pretty well, but not if two patterns overlap: /abc/ and /bcd/, matching on the string "abcd", for example, will fire only on "abc", and miss the "bcd" hit.

Given this, it appears the only option is to run the trie match, and then iterate on all the regexps for the base strings it contains:

  if ($line =~ m{hello|hi|foo}) {
    $line =~ /hello/ and rule_fired("HELLO");
    $line =~ /hi/ and rule_fired("HI");
    $line =~ /foo/ and rule_fired("FOO");
  }

Obviously, that doesn't provide much of a speedup -- in fact, so far, I've been unable to get any at all out of this method. :(

This can be optimized a little by breaking into multiple trie/match sets:

  if ($line =~ m{hello|hi}) {
    $line =~ /hello/ and rule_fired("HELLO");
    $line =~ /hi/ and rule_fired("HI");
    ...
  }
  if ($line =~ m{foo|bar}) {
    $line =~ /foo/ and rule_fired("FOO");
    $line =~ /bar/ and rule_fired("BAR");
    ...
  }

But still, the reduction in regexp OPs vs the addition of logic OPs to do this, result in an overall slowdown, even given the faster trie-based REs.

Suggestions, anyone?

(by the way, if you're curious, the current code is here in SVN.)

aho-corasick hacking optimisation perl regexps spamassassin tries

A Guinness 419 scam!

I may be a bit hungover this Sunday morning due mainly to the effects of the subject of this post, but -- Guinness National Lottery? is anyone going to fall for that?

From: hamilton jones <hamilton_jones2006@yahoo.it>
Subject: GUINNESS. CUSTORMERS PROMOTION

GUINNESS. CUSTORMERS PROMOTION
dv-2006 program
guinness plc, West Africa.
st christo road (ecowas)

                                    FINAL_ NOTIFICATION.

We happily inform you about our (guinness. national lottery
program)held on the 10th of november 2006, which you enterd as a
dependent client and finally took the 1st position in our second
(2nd) category winners, that falls within  the europe region Manchester Uk.
Your email was attached to the ticket number(44-40-23-777-01) which
made you a winner of (us$500,000.00) and your name being recorded in
our guinness world book of record as the 1st lucky winner of the year
2006. You have been approved the sum of US$500,000.00 which will be
sent accross to you immediately.

All emails are selected randomly through a computer ballot which
subsequently won you the sweepstakes of Guinness internet web
lottery.

CONGRATULATIONS YOU EMERGED OUR WINNER!!!
= = = = = = = = = = = = = = = = = = = = = = = = = = =
This is part of our security measures put in place to avoid double
claiming or a situation where unwanted person(s) would be taking
Negative advantage of these promotions, thereby impersonating in
order to claim another persons winning prize.
Here is our fiduciary agent responsible for your the processing /
Release of winnings for all Second Category winners where your
winning Falls into:
MR HAMILTON JONES
EMAIL: hamilton_jones2006@yahoo.it

GUINNESS. CLAIMING SECURITY AGENT.
= = = = = = = = = = = = = = = = = = = = = = = = = = =
You are required to forward the following details to help facilitate
the processing of your GUINNESS. CLAIMS OF CERTIFICATE.

Full names / Residential address / Phone number / Occupation / Sex /
Age / Present country / Marital status.

ONCE AGAIN CONGRATULATION!!!!
Yours sincerely

ANDERSON HEGLAND

ireland anti-spam spam

Irish Blogs top 100 -- should old blogs be trimmed?

Over on the Technorati Top 100 of Irish Blogs list, I've noticed something; quite a few of the listings have stopped publishing, such as number 5, Tom Murphy's Natterjackpr.com.

I'm wondering -- should no-longer-publishing blogs be listed? Technorati still keeps their ranking high -- clearly old data is not expired from the Technorati database for at least a year. But maybe my scripts should use last-post-published time, from planet.journals.ie where available, and discard blogs that haven't put anything up in something like 4 months.

What do you think?

blogs irishblogs technorati top-100

Top 100 Irish Blogs, pt 2

The previous post was pretty popular, and one of the requests was for a regularly-updated listing. So here it is: http://taint.org/technorati/

Since Technorati limit daily queries to about 500 per day (iirc), and there are quite a few more blogs in the Irish blogs list, I plan to update it on a nightly basis, with each set of blogs updating on different days. This should result in the figures staying more-or-less up to date without hammering T'rati too much.

blogging blogs hacks ireland top100

Gastric woes

milkncheese.jpgObservant taint.org readers might recall me complaining about a bout of food poisoning back in June during ApacheCon week, which, along with a poorly-timed work trip, unfortunately managed to stop me attending ApacheCon altogether.

Turns out that that "food poisoning" never went away -- four months later, I'm still having digestive troubles. However, I've been lucky enough to figure out a way to minimise it, which I'll mention here for posterity (and Google).

So, basically, the symptoms were general stomach unsettledness, nausea, cramping, a sharp pain in the right side, and heartburn -- all waxing and waning intermittently. (There were issues at "the other end" I'll leave out, in the interests of good taste.) On top of that, my level of stomach "calmness" was way off -- nausea from travelling in cars, buses, taxis etc. became an issue.

Thankfully, it didn't interfere with work much at all -- since I work from home, it was pretty easy to deal with. But it certainly put a damper on trips like ApacheCon, or BarCamp Ireland... it became quite difficult, in particular, to travel any kind of distance during the daytime. (Luckily my ability to partake in pints of Guinness during the evening was not affected, however. ;)

I did the usual thing of visiting my local G.P., and was referred to a gastro-intestinal specialist -- that's all still going on, slowly. But fortunately, in the meantime, I had a breakthrough in terms of dealing with the symptoms.

Initially, the waxing and waning of symptoms seemed pretty random, but after a week or two, a pattern emerged -- on a normal day, it'd typically be worst at about 11am in the morning, then ease off before lunch, then worse again after lunch. During and after dinner, it'd be fine, and the evenings were almost symptom-free. On an empty stomach, there was similarly virtually no problems whatsoever.

Of course, having a link with quantities of food makes sense for a GI illness. But it eventually occurred to me that the symptoms were increasing and waning in time with specific types of food, in fact. The pattern of symptoms were tracking my drinking of milk, in cereal, and in tea or coffee, delayed by about 2 hours. Now, I've always been a total omnivore -- I've never suffered from allergies, had any issues digesting food, or suffered travel illness. My sea legs were rock solid; one trip to the Great Barrier Reef saw myself and C being the only tourists not to vom over the sides despite some heavy waves. Also, as an Irishman, tea is the core component of my diet, and tea with milk at that; and dairy is similarly at the heart of Irish cuisine in many ways, plenty of milk, cheese, and butter. I was raised on the stuff, and love it!

But the signs were pretty solid, so I gave up dairy for a week or two to try it out. It took a week to "clear out" initially, but since then, the results have been fantastic; some of the symptoms (the sharp pain, cramps, heartburn) are almost gone, and levels of the others (nausea, stomach 'unsettledness') are way down most of the time. If I eat something that contains milk, cheese or whey -- such as a packet of crisps recently -- I can tell within 10 minutes, since the pain in my right side "twinges" noticeably. It really is astounding.

The wierd thing is, this came out of nowhere. A week before that bbq, I was glugging milk without a single issue, and feeling perfectly fine; I've never had issues with dairy. Then all of a sudden, it just hit me, seemingly after a short bout of food poisoning, and it still hasn't gone away.

Talking to people, though, it appears this is more common than one might think; I now know of several people who've become lactose intolerant, suddenly, in their 30s.

Anyway, the core issue is still there, but while the wheels of medical science grind on, I at least have pretty good control of the nastier symptoms again. yay.

dairy food life stomach

Technorati-ranked Irish Blogs Top 100

So, I was thinking about the various Irish blog aggregators, Planet.journals.ie, IrishBlogs.ie, and IrishBlogs.info. Michele's Irishblogs.info attempts to "rank" the blogs by hits, but many of the Irish webloggers don't include that hit-counting HTML snippet in their web pages, so quite a few are probably missing; on top of that, RSS readers don't count. It lists me as #3, which I knew was definitely wrong, anyway ;)

However, it occurred to me that an alternative way to compute a "top 100" would be to use the Technorati rank of each blog, and make a table based on that; that'd measure the blogs by Technorati's readership-estimation algorithm, which may still be faulty, of course, but worth a try... I was curious, so I gave it a go, and here's the results. Enjoy!

Update: This table is no longer up-to-date -- a much fresher version is now available over here, and will be updated regularly.

Top 100 by rank / inbound blog links:

Position Rank Inbound blogs Inbound links Blog
1 2940 638 1931   http://www.tomrafteryit.net/
2 6636 371 1280   http://www.mulley.net/
3 8231 315 625   http://twentymajor.blogspot.com/
4 10984 249 512   http://www.natterjackpr.com/
5 15720 181 409   http://www.avalon5.com/
6 18897 151 315   http://irish.typepad.com/irisheyes/
7 19364 148 472   http://www.gavinsblog.com/
8 21214 136 385   http://www.blather.net/
9 21715 133 968   http://ocaoimh.ie/
10 22210 132 399   http://eirepreneur.blogs.com/eirepreneur/
11 22258 130 323   http://thetorturegarden.blogspot.com/
12 23921 122 351   http://www.dehora.net/journal/
13 24143 121 199   http://www.atlanticblog.com/
14 24828 118 174   http://freestater.blogspot.com/
15 25570 115 260   http://arseblog.com/WP
16 25570 115 246   http://tcal.net/
17 27174 109 252   http://www.digitalrights.ie/
18 27189 110 169   http://cork2toronto.blogspot.com/
19 28004 106 731   http://taint.org/
20 29008 103 286   http://unitedirelander.blogspot.com/
21 29008 103 232   http://www.nialler9.com/blog
22 29008 103 175   http://clickhere.blogs.ie/
23 29978 100 270   http://www.mneylon.com/blog
24 31954 95 901   http://www.irishelection.com/
25 33397 91 231   http://memex.naughtons.org/
26 34121 89 370   http://siciliannotes.blogspot.com/
27 35022 86 285   http://www.sineadgleeson.com/blog
28 35022 86 146   http://www.cfdan.com/
29 35858 84 904   http://www.pkellypr.com/blog
30 36223 84 255   http://www.thinkingoutloud.biz/
31 37735 80 175   http://www.dervala.net/
32 39719 76 207   http://backseatdrivers.blogspot.com/
33 40078 76 229   http://fdelondras.blogspot.com/
34 40276 75 203   http://www.mediangler.com/
35 40821 74 128   http://www.thinkinghomebusiness.com/blog
36 44148 69 122   http://outofambit.blogspot.com/
37 45075 67 147   http://www.podleaders.com/
38 45075 67 87   http://www.aidanf.net/
39 45729 66 238   http://www.argolon.com/
40 46477 65 201   http://www.sarahcarey.ie/
41 46477 65 191   http://disillusionedlefty.blogspot.com/
42 47586 64 141   http://www.johnbreslin.com/blog
43 48011 63 66   http://www.branedy.net/
44 52278 58 398   http://dossing.blogspot.com/
45 54710 56 155   http://redmum.blogspot.com/
46 55758 55 103   http://richarddelevan.blogspot.com/
47 56390 54 148   http://donal.wordpress.com/
48 56390 54 129   http://prettycunning.net/blog
49 57527 53 104   http://www.dublinblog.ie/
50 58724 52 167   http://www.tuppenceworth.ie/blog
51 58724 52 102   http://www.inter-actions.biz/blog/
52 59920 51 101   http://seanmcgrath.blogspot.com/
53 60315 51 76   http://www.blackphoebe.com/msjen/
54 62483 49 112   http://www.infactah.com/
55 62885 49 118   http://mamanpoulet.blogspot.com/
56 63869 48 229   http://icecreamireland.com/
57 68503 45 93   http://www.web2ireland.org/
58 68503 45 75   http://www.davidmcwilliams.ie/
59 68503 45 73   http://vipglamour.net/
60 68824 45 193   http://imeall.blogspot.com/
61 72248 43 81   http://planetpotato.blogs.com/planet_potato_an_irish_bl/
62 73843 42 149   http://lettertoamerica.blogs.com/
63 73843 42 119   http://www.kenmc.com/
64 73843 42 102   http://www.pmooney.net/blogsphe.nsf
65 73843 42 70   http://bohanna.typepad.com/pureplay/
66 75725 41 107   http://bonhom.ie/
67 75725 41 93   http://www.bibliocook.com/
68 75725 41 78   http://shittyfirstdraft.blogspot.com/
69 77680 40 225   http://bestofbothworlds.blogspot.com/
70 77680 40 134   http://www.stdlib.net/%7Ecolmmacc
71 77957 40 82   http://davesrants.com/
72 79732 39 103   http://ricksbreakfastblog.blogspot.com/
73 80012 39 92   http://manuel-estimulo.blogspot.com/
74 81970 38 91   http://gingerpixel.com/
75 82240 38 248   http://www.linksheaven.com/
76 84304 37 726   http://thelimerick.blogspot.com/
77 84304 37 127   http://www.ryderdiary.com/
78 84304 37 83   http://morgspace.net/
79 84304 37 64   http://talideon.com/weblog/
80 86729 36 140   http://www.damienblake.com/
81 86729 36 124   http://irisheagle.blogspot.com/
82 86729 36 102   http://blog.rymus.net/
83 86729 36 65   http://www.adammaguire.com/blog
84 87068 36 272   http://progressiveireland.blogspot.com/
85 89814 35 145   http://www.windsandbreezes.org/
86 92646 34 43   http://football-corner.blogspot.com/
87 95258 33 207   http://www.fustar.org/
88 95258 33 171   http://www.iced-coffee.com/
89 95258 33 82   http://www.bytesurgery.com/gearedup
90 101881 31 90   http://phoblacht.blogspot.com/
91 101881 31 70   http://counago-and-spaves.blogspot.com/
92 101881 31 58   http://www.firstpartners.net/blog
93 105668 30 82   http://realitycheckdotie.blogspot.com/
94 109643 29 142   http://bifsniff.com/cartoons/
95 109643 29 75   http://dave.antidisinformation.com/
96 109643 29 60   http://conoroneill.com/
97 109643 29 55   http://www.minds.may.ie/%7Edez/serendipity/
98 109643 29 51   http://dublin.metblogs.com/
99 110005 29 78   http://www.janinedalton.com/blog
100 110005 29 54   http://www.runningwithbulls.com/blog

List by inbound links:

Position Rank Inbound blogs Inbound links Blog
1 2940 638 1931   http://www.tomrafteryit.net/
2 6636 371 1280   http://www.mulley.net/
3 21715 133 968   http://ocaoimh.ie/
4 35858 84 904   http://www.pkellypr.com/blog
5 31954 95 901   http://www.irishelection.com/
6 28004 106 731   http://taint.org/
7 84304 37 726   http://thelimerick.blogspot.com/
8 8231 315 625   http://twentymajor.blogspot.com/
9 258886 13 519   http://newswire99.blogspot.com/
10 10984 249 512   http://www.natterjackpr.com/
11 19364 148 472   http://www.gavinsblog.com/
12 164780 20 451   http://inao.blogspot.com/
13 15720 181 409   http://www.avalon5.com/
14 22210 132 399   http://eirepreneur.blogs.com/eirepreneur/
15 52278 58 398   http://dossing.blogspot.com/
16 21214 136 385   http://www.blather.net/
17 34121 89 370   http://siciliannotes.blogspot.com/
18 23921 122 351   http://www.dehora.net/journal/
19 156276 21 336   http://www.ebbybrett.co.uk/blog
20 22258 130 323   http://thetorturegarden.blogspot.com/
21 18897 151 315   http://irish.typepad.com/irisheyes/
22 29008 103 286   http://unitedirelander.blogspot.com/
23 35022 86 285   http://www.sineadgleeson.com/blog
24 87068 36 272   http://progressiveireland.blogspot.com/
25 239963 14 271   http://www.thehealthtechblog.com/
26 29978 100 270   http://www.mneylon.com/blog
27 25570 115 260   http://arseblog.com/WP
28 36223 84 255   http://www.thinkingoutloud.biz/
29 27174 109 252   http://www.digitalrights.ie/
30 82240 38 248   http://www.linksheaven.com/
31 977738 3 248   http://www.tomgriffin.org/the_green_ribbon/
32 25570 115 246   http://tcal.net/
33 45729 66 238   http://www.argolon.com/
34 29008 103 232   http://www.nialler9.com/blog
35 33397 91 231   http://memex.naughtons.org/
36 40078 76 229   http://fdelondras.blogspot.com/
37 63869 48 229   http://icecreamireland.com/
38 77680 40 225   http://bestofbothworlds.blogspot.com/
39 208904 16 210   http://www.anlionra.com/
40 471327 7 208   http://www.ravenfamily.org/sam/
41 39719 76 207   http://backseatdrivers.blogspot.com/
42 95258 33 207   http://www.fustar.org/
43 40276 75 203   http://www.mediangler.com/
44 46477 65 201   http://www.sarahcarey.ie/
45 637233 5 200   http://armchaircelts.co.uk/
46 24143 121 199   http://www.atlanticblog.com/
47 280786 12 199   http://conann.com/
48 68824 45 193   http://imeall.blogspot.com/
49 46477 65 191   http://disillusionedlefty.blogspot.com/
50 637233 5 182   http://www.everysecondpaycheck.com/blog
51 164524 20 181   http://irishlinks.blogspot.com/
52 542250 6 176   http://www.dublinka.com/
53 29008 103 175   http://clickhere.blogs.ie/
54 37735 80 175   http://www.dervala.net/
55 24828 118 174   http://freestater.blogspot.com/
56 155943 21 172   http://www.jamesgalvin.com/
57 95258 33 171   http://www.iced-coffee.com/
58 164524 20 171   http://irishcraftworker.typepad.com/an_irish_craftworkers_goo/
59 27189 110 169   http://cork2toronto.blogspot.com/
60 58724 52 167   http://www.tuppenceworth.ie/blog
61 141242 23 164   http://atp.datagate.net.uk/blog
62 148304 22 159   http://www.lifewithouttoast.com/
63 184241 18 158   http://funferal.org/
64 54710 56 155   http://redmum.blogspot.com/
65 73843 42 149   http://lettertoamerica.blogs.com/
66 56390 54 148   http://donal.wordpress.com/
67 45075 67 147   http://www.podleaders.com/
68 155943 21 147   http://dublinopinion.com/
69 35022 86 146   http://www.cfdan.com/
70 89814 35 145   http://www.windsandbreezes.org/
71 109643 29 142   http://bifsniff.com/cartoons/
72 195745 17 142   http://podcasting.ie/podcast
73 47586 64 141   http://www.johnbreslin.com/blog
74 86729 36 140   http://www.damienblake.com/
75 223280 15 137   http://thegurrier.com/
76 77680 40 134   http://www.stdlib.net/%7Ecolmmacc
77 980795 3 131   http://www.sineadcochrane.com/
78 56390 54 129   http://prettycunning.net/blog
79 40821 74 128   http://www.thinkinghomebusiness.com/blog
80 84304 37 127   http://www.ryderdiary.com/
81 86729 36 124   http://irisheagle.blogspot.com/
82 44148 69 122   http://outofambit.blogspot.com/
83 73843 42 119   http://www.kenmc.com/
84 62885 49 118   http://mamanpoulet.blogspot.com/
85 135121 24 117   http://nellysgarden.blogspot.com/
86 195745 17 115   http://blog.infurious.com/
87 542250 6 114   http://ainelivia.typepad.com/aine_livia_at_the_midnigh/
88 62483 49 112   http://www.infactah.com/
89 75725 41 107   http://bonhom.ie/
90 57527 53 104   http://www.dublinblog.ie/
91 55758 55 103   http://richarddelevan.blogspot.com/
92 79732 39 103   http://ricksbreakfastblog.blogspot.com/
93 58724 52 102   http://www.inter-actions.biz/blog/
94 73843 42 102   http://www.pmooney.net/blogsphe.nsf
95 86729 36 102   http://blog.rymus.net/
96 59920 51 101   http://seanmcgrath.blogspot.com/
97 173857 19 99   http://www.ofoghlu.net/log/
98 118678 27 96   http://irishkc.com/
99 68503 45 93   http://www.web2ireland.org/
100 75725 41 93   http://www.bibliocook.com/

Update: Here's a full list of all 569 tested blogs. Also, there's been a minor change to the rankings here; I've just realised that there was a bug in how the script handled evenly-matched blogs, so (for example) #15 and #16 were reversed in order; that's now fixed.

If you find a blog missing, it's possible that (a) it's not pinging Planet.journals.ie or (b) is not registered with Technorati; this method requires both of those. Most Irish blogs do, but some (Old Rotten Hat, for example) don't...

Methodology

I found this more-or-less full list of Irish weblogs at Planet.journals.ie, and selected the blogs that had pinged their site in the past 6 months, then cut that down to just the blog main-page URLs, removing duplicates.

Given that list, I then looked up each blog URL using the Technorati API, and got its rank, inbound link count, and inbound linking blogs count.

top100code.tgz is a tarball of the perl code I wrote to do this, if you fancy doing it yourself on whichever set of blogs you fancy...

blogging blogs hacks ireland top100

Maximise value, not protection (fwd)

Here's an excellent quote from the OpenGeoData weblog, really worth reproducing:

''We think the natural tendency is for producers to worry too much about protecting their intellectual property. The important thing is to maximise the value of your intellectual property, not to protect it for the sake of protection. If you lose a little of your property when you sell it or rent it, that's just a cost of doing business, along with depreciation, inventory losses, and obsolescence.'' -- Information Rules, Carl Shapiro and Hal Varian, page 97.

Words to live by!

carl-shapiro drm hal-varian intellectual-property ip open-culture open-source property

The vagaries of Google Image Search

Remember the C=64-izer, the quick hack to display an image in the style of the Commodore 64?

Recently, I've started getting hits to this demo image of the "O RLY?" owl -- lots of 'em.

It turns out that the C=64-ized rendition of this image is now the top hit for "O RLY" on Google Image Search; pretty bizarre, since there are obvious better images on the first search page, one result along in fact. What's more, the page listed as the 'origin page', http://taint.org/tag/today, doesn't even use that text.

This has resulted in lots of Myspace kiddies etc. obliviously using the C=64 rendering. Yay for Commodore ;)

c64 c64izer commodore google hacks images o-rly

VISA and priorities

A couple of years ago, various anti-spammers discussed how the credit-card payment processing companies were perfectly placed to disrupt the spam economy, by tracking down spammers through "poison pill" transactions. Nothing happened from that, though, and spam is now a bigger problem than ever.

Today, I hear that the Russian MP3 site, AllOfMP3, have lost their account with Visa to process credit-card payments.

In other words, it sounds like the banks are happy enough to close off filesharing, but couldn't be bothered dealing with spam...

allofmp3 anti-spam credit-cards filesharing payments visa

Ireland now has RFID passports

Back in February, I wrote about some Dutch hackers remotely reading Dutch RFID passports, and my email to the Irish Passport Office enquiring about their plans.

They never bothered writing back; I guess they were too busy implementing the damn things :( Their new 'ePassports' are now mandatory for new Irish passports:

The chip technology allows the information stored in an Electronic Passport to be read by special chip readers at a close distance.

"special chip readers at a close distance" and/or "random criminals looking for Irish victims at a distance of 30 feet", I guess.

Here's the slides for Riscure's attack on the Dutch passports. Irish passports are similarly using "Basic Access Control". I wonder if Irish passport numbers are sequential, since that seems to be a key part of their attack?

epassports hacking ireland passports rfid riscure

DIY Glory

It's been a while since I've embarked on a DIY job around the house with quite as much success as the most recent one -- laying and tacking down some new carpet in the front hall. The last job was a bike rack, which had to be abandoned after the 4-inch screws proved too loose and threatened to fall out of the wall, leaving gigantic plugs of Polyfilla in their place (I'm sure bad drilling had nothing to do with it).

This has all now been forgotten in the glory of the freshly-laid carpet. Now, every time I walk past the front hall, I have to stick my head in and check out the perfectly-fitted carpet with pride. This can only last so long before my next botch job, of course...

diy house life

Anti-spam group under attack -- via ICANN

[This is a copy of an article I submitted to ICANNWatch.]

Spamhaus, the UK-based non-profit that runs the SBL and XBL anti-spam DNS blocklists, is reportedly facing serious legal trouble in the US.

A US-based spam gang has started legal action to have Spamhaus' domain name confiscated by ICANN, and reportedly, Spamhaus may have been advised badly by their US legal people; so there is now a danger that they *may* indeed lose their domain, and possibly worse.

Note that Spamhaus is entirely UK-based, bar some mirrors; however, the proposed order is aimed at ICANN, which is US-based. This is the really tricky part; can a US company kill the domain of a non-US group?

According to anti-spam lawyer Matthew Prince, 'there may be some time before ICANN is formally ordered to shut down the Spamhaus domain, but make no mistake that ICANN's lawyers will be considering their options beginning first thing Monday, if they haven't already begun the conference calls tonight' ... 'In the end, [ICANN's] decision is likely to be much more about setting a general policy than the specific details of who Spamhaus is or why they are critical for the Internet. ICANN will desperately want to stay out of this dispute, but they are subject to U.S. law and they will probably have attorneys who will argue they need to follow it. All it will take for this to end badly for Spamhaus is one lawyer at ICANN getting a little bit spooked and Spamhaus could lose not only it's .org but potentially any other TLD that ICANN controls.'

This is interesting -- if Spamhaus is forced to close down its domains and US-based mirrors, that will mean that the SBL and XBL blocklists will be down for a while, too. Typically those are used for up-front blocking, and if my servers are any indication, they take care of 75% of incoming spam before it hits any more CPU-intensive filtering.

Without those, there'll be a lot of sites around the net suddenly dealing with quadrupled spam volumes hitting their MTAs.

anti-spam e360 icann jurisdiction law spamhaus

NEDAP voting machines hacked

Here's a press release from ICTE that's well worth a read if you still trust voting machines:

Concerns expressed by many IT professionals about the security of the e-voting system chosen for use in Ireland were today shown to be well-founded when a group of Dutch IT Specialists, using documentation obtained from the Irish Department of the Environment, demonstrated that the NEDAP e-voting machines could be secretly hacked, made to record inaccurate voting preferences, and could even be secretly reprogrammed to run a chess program.

The recently formed Dutch anti e-voting group, "Wij vertrouwen stemcomputers niet" (We don't trust voting computers), has revealed on national Dutch television program "EenVandaag" on Nederland 1, that they have successfully hacked the Nedap machines -- identical to the machines purchased for use in Ireland in all important respects.

ICTE representative Colm MacCarthaigh, who has seen and examined the compromised Nedap machine in action in Amsterdam, notes "The attack presented by the Dutch group would not need significant modification to run on the Irish systems. The machines use the same construction and components, and differ only in relatively minor aspects such as the presence of extra LEDs to assist voters with the Irish voting system. The machines are so similar that the Dutch group has been using only the technical reference manuals and materials relevant to the Irish machines as a guide, as those are the only materials publicly available."

Maurice Wessling, of Wij vertrouwen stemcomputers niet, adds "Compromising the system requires replacing only a single component, roughly the size of a stamp, and is impossible to detect just by looking at the machine".

Both ICTE and Wij vertrouwen stemcomputers niet view this as yet another demonstration that no voting system which lacks a voter-verified audit trail can be trusted. According to ICTE spokesperson Margaret McGaley "Any system which lacks a means for the voter to verify that their vote has been correctly recorded is fundamentally and irreparably flawed".

Margaret McGaley highlighted that it is the machines themselves that are at risk. "This particular issue is not about the vote counting software, which we already know must be replaced, this is about the machines that the Taoiseach has claimed were 'validated beyond any question'. We now have proof that these machines can be made to lie about the votes that have been cast on them. It is abundantly clear that these machines would pose a genuine risk to our democracy if used in elections in Ireland."

ICTE is repeating its call, which reflects the opinions shared by IT expert groups, including the E-voting group of the Irish Computing Society, that any voting system implemented must include a voter-verified audit-trail.

This is a major exploit. Colm's earlier mail noted

As we knew already, the machines run on m64k processors, and it's relatively easy to reverse engineer what all of the registers and inputs correspond to. The dutch group were able to successfull assemble code to run on the machine, and even burn it on the very eeprom that comes in the machine.

Since the NEDAP design does not include XBox-style boot-time cryptographic verification of the EEPROM's contents, undetectable replacement of the operating system is a 2-minute matter of unsticking the trivial 'seals' on the voting machine's access panels, popping out an EEPROM chip, and replacing with a modified one, then closing it up again.

Once that's done, the election is rigged, as WVSN have demonstrated.

Update: here's their paper describing the attack in detail -- well worth a read.

e-voting icte nedap wvsn

a plug for Map24

Nat at O'Reilly Radar mentions that Multimap have added a public API . It's great to see more sites adding public APIs, but sadly, as I note in a comment there, Multimap isn't any use for me -- they, along with Google and Yahoo!, have really crappy Irish mapping. Their geocoders (the part that turns an english-language address into a GIS coordinate pair) are pretty much non-functional for Ireland.

I moved from the US to Ireland earlier this year and found this pretty frustrating, after the joys of using the US mapping sites to get driving directions etc.

Thankfully, another contender has emerged recently -- Map24.

They have a great geocoder for Ireland, and very reliable directions, which are even accurate for some of the more baroque one-way-system traffic-management changes that Dublin's city planning department have come up with recently. The look and feel of the website is a little clunky in Firefox -- not as smooth as Google's -- but it has some nice AJAXy touches now and seems to be heading in the right direction.

Interestingly, they now offer a public API for third-party mashups, and even offer an API for their geocoder -- so someone preferring the Google look and feel could mash that up, using Map24 to find the coordinates and Google to display an area map! (Actually, I think that may be how John Handelaar's earlier hack worked -- I note in the comments that he mentions Map24 provide Lycos' mapping backend. aha.)

Anyway -- Map24 -- if you're looking for a good Irish mapping/driving-directions site, it'll do the trick.

directions dublin geocoders google ireland map24 mapping multimap yahoo

Some p0f Data From Craig

Regarding the use of p0f, passive OS fingerprinting, as an anti-spam measure -- on top of this analysis which I linked to a few weeks back, one of the emeritus SA guys, Craig Hughes, sends over some p0f experiences. Handily, this includes a more detailed breakdown by OS release:

I've been using the SA p0f plugin for nearly a month or so now both on gumstix's web server and my hughes-family.org server, and it actually looks like it could be pretty useful. So far I've just been scoring 0.001 for each OS to collect data, but here's the results amavis has logged:

This breakdown shows what %age of the stuff coming in via OS xyz is spam or ham. ie 84.6% of all mail received from Windows-2000 is spam, 14.9% is ham (the rest is viruses). The first numeric column is number of messages of each type. Statistics are only since the last time amavis restarted:

On his home machine (comcast cable modem connection) :

spam.byOS.Windows-2000438 1/h 84.6 %
spam.byOS.Linux417 1/h 18.3 %
spam.byOS.Windows-XP265 1/h 97.8 %
spam.byOS.UNKNOWN135 0/h 55.1 %
spam.byOS.Windows-XP/200024 0/h 100.0 %
spam.byOS.Novell5 0/h 100.0 %
spam.byOS.Windows-983 0/h 60.0 %
spam.byOS.Windows-20032 0/h 66.7 %
spam.byOS.FreeBSD2 0/h 1.3 %
spam.byOS.Solaris1 0/h 1.8 %
spam.byOS.Windows-SP31 0/h 100.0 %
ham.byOS.Linux1851 6/h 81.2 %
ham.byOS.FreeBSD143 0/h 96.0 %
ham.byOS.UNKNOWN102 0/h 41.6 %
ham.byOS.Windows-200077 0/h 14.9 %
ham.byOS.Solaris56 0/h 98.2 %
ham.byOS.NetCache6 0/h 100.0 %
ham.byOS.Windows-XP6 0/h 2.2 %
ham.byOS.Tru642 0/h 100.0 %
ham.byOS.AIX2 0/h 100.0 %
ham.byOS.Windows-982 0/h 40.0 %
ham.byOS.Windows-20031 0/h 33.3 %

On gumstix.com (hosted at some provider in Texas):

spam.byOS.Windows-2000 401 1/h 58.4 %
spam.byOS.Windows-XP 131 0/h 92.9 %
spam.byOS.UNKNOWN 64 0/h 18.7 %
spam.byOS.Windows-XP/2000 29 0/h 96.7 %
spam.byOS.FreeBSD 11 0/h 4.1 %
spam.byOS.Linux 11 0/h 0.5 %
spam.byOS.Windows-98 6 0/h 85.7 %
spam.byOS.Solaris 4 0/h 3.3 %
spam.byOS.Windows-SP3 2 0/h 100.0 %
ham.byOS.Linux 1983 4/h 97.6 %
ham.byOS.UNKNOWN 277 0/h 80.8 %
ham.byOS.Windows-2000 271 0/h 39.4 %
ham.byOS.FreeBSD 253 0/h 93.7 %
ham.byOS.Solaris 116 0/h 96.7 %
ham.byOS.NetCache 40 0/h 100.0 %
ham.byOS.Windows-XP 9 0/h 6.4 %
ham.byOS.Windows-NT 7 0/h 70.0 %
ham.byOS.Novell 3 0/h 100.0 %
ham.byOS.Windows-XP/2000 1 0/h 3.3 %
ham.byOS.Windows-98 1 0/h 14.3 %
ham.byOS.Windows-2003 1 0/h 100.0 %

my home machine has a lot more relayed mail coming to it (all my various craig@* email addresses forward into there) which is probably why the linux spam rate is higher there -- the relaying machines are probably running linux and forwarding spam through.

Interesting figures -- but I'm still not-convinced that the correlation is quite high enough to form a good enough basis for solid anti-spam rules; reliable rules in the SpamAssassin core typically have over 95% accuracy at differentiating ham from spam (at least when we first check them in).

Update: it's a natural for use as a Bayes token, though. The way amavisd-new implements p0f support is perfect for this use.

BTW, my guess is that many of the spam hits for "linux" are due to things like Netgear/Linksys routers, running embedded linuces. No evidence, just guessing ;)

anti-spam craig fingerprinting p0f spamassassin

Linus on Bayesian filtering

Linus Torvalds, in a post to linux-kernel today:

I'm sorry, but spam-filtering is simply harder than the bayesian word-count weenies think it is. I even used to know something about bayesian filtering, since it was one of the projects I worked on at uni, and dammit, it's not a good approach, as shown by the fact that it's trivial to get around.

I don't know why people got so excited about the whole bayesian thing. It's fine as one small clause in a bigger framework of deciding spam, but it's totally inappropriate for a "yes/no" kind of decision on its own.

If you want a yes/no kind of thing, do it on real hard issues, like not accepting email from machines that aren't registered MX gateways. Sure, that will mean that people who just set up their local sendmail thing and connect directly to port 25 will just not be able to email, but let's face it, that's why we have ISP's and DNS in the first place.

But don't do it purely on some bogus word analysis.

If you want to do word analysis, use it like SpamAssassin does it - with some Bayesian rule perhaps adding a few points to the score. That's entirely appropriate. But running bogo-filter instead of spamassassin is just asinine.

Me, I like bogofilter -- those guys are cool, and it's a great anti-spam product for many purposes. But of course I have to agree with Linus that the correct approach in most cases is a bigger picture than just Bayes alone, a la SpamAssassin ;)

anti-spam bayes linus-torvalds spamassassin

Back in one piece

Well, I'm back in Dublin in one piece, after a great honeymoon in Corsica. Lots of stuff to catch up on, so if you're waiting on a response, sorry, it might take a little longer...

honeymoon life meta wedding

Hitched! Pt. 2

Well, the second half of the wedding -- the fun part, with dinner, dancing, friends, and family -- went off without a hitch. Our hippy-crap-laden humanist ceremony, celebrated with the aid of our friend Gerry, was a great success; the pianist and various DJs provided fantastic aural accompaniment; and the venue, Markree Castle in County Sligo, was fantastic, taking care of the entire party in every way we hadn't foreseen and putting up with us far into the early hours of the next day.

That was the most fun I've had in yonks, and thanks to everyone who came. (And those who didn't, due to the whims of US visa conditions -- you were much missed.)

Photos will follow once we're back from the honeymoon, which starts tomorrow morning. later ;)

fun hitched life married wedding

BarCamp Ireland

wow, BarCamp Ireland is really shaping up!

Unfortunately, it's very unlikely that I'll be able to make it, due to all the wedding/honeymoon activity around that time (and it being down in Cork, which is a bit of a nontrivial journey at the moment). Pity, it looks like it'll be great -- and could probably do with some more talks about open source, to go with all the web2.0/startup content ;)

barcamp barcampireland cork ireland

SpicyLinks and del.icio.us Network Summarization

Ross Mayfield:

Every time I see Gabe Rivera of TechMeme, I ask for the same thing -- MeMeme. Give me TechMeme where the core index is based on who I read, about 150 people at any given time, to show me what my friends are interested in.

Funnily eough, that is exactly why I wrote SpicyLinks!

It works pretty well -- in fact, nowadays I don't really bother reading slashdot, Digg, Reddit, et al, particularly frequently, because I know that all the really interesting stuff will be at the top of my newsreader in the SpicyLinks feed.

Anyway, I've been calling SpicyLinks a 'summarizing aggregator', but the discussion that arose from Ross' posting inspired me. A little bit of hacking has come up with an interesting twist: take a del.icio.us social network, a CGI script called deliciousnetwork2opml.cgi, and 15 minutes hacking on SpicyLinks to support inclusion of OPML via a remote URI, and hey presto -- it's now a social-network summarising aggregator. ;)

aggregation delicious hacks link-blogs rss social-networking software spicylinks

Unblocked

I just found an error in an Apache config file for taint.org, resulting in some of the legacy RSS feed URLs producing invalid data -- this meant that anyone subscribed to the Feedburner feed, for example, had been missing out on my witterings. Fixed now -- apologies!

feedburner feeds meta rss

Flickr's Lousy US-Only Maps

Update: This is now fixed. See here for details...

Here's the 2lmc boys getting rightly annoyed about Flickr's new mapping feature, which displays geotagged photos overlaid on a mapping UI -- as they note, it's basically a steaming pile of crap outside the US:

However, because Flickr are owned by Yahoo, they're using their maps. And, like all Yahoo! products, if you're not American, it sucks.

Compare this lovely data-rich map of SF:

sf

With this featureless grey blob:

dublin

That's just pathetic -- there isn't a single place name visible, and even the Phoenix Park, the biggest urban park in Europe, is simply displayed just as a light-coloured splat with a road going through it.

It appears the Yahoo! mapping data for the UK and Ireland just isn't really there. What someone needs to do, is take the geotagging data from Flickr, and overlay it on the far more informative Google map data instead ;):

dublin google

It's a real shame -- I used to rely on Y! Maps to get directions everywhere while in the US. They're missing out on so many customers here...

Update: good news -- the Flickr maps are now things of beauty to match Google's:

flickr-fixed.gif

flickr geodata geotagging insularity ireland mapping yahoo

Hitched!

Yesterday was spent in the beautiful surrounds of Naas Leisure Centre, attending the Kildare Registry Office for a brief ceremony and some putting of pen to paper -- and hey presto, myself and the lovely C are now husband and wife ;) About time, really -- we've been going out for 13 years, after all.

This is just the legal preliminaries -- the big party is two weeks from now, in a castle in Sligo, and it's shaping up to be a great party. But still, legally, she's my wife now...

By the way, one bonus of getting the legal stuff out of the way in advance is that we now don't have to have all the fun marred by legal requirements on the big day. As a result, our mate Gerry, who a few taint.org readers will know, will be presiding over the real wedding ceremony. ;)

ireland politics dublin

The EHIC and Irish government websites

The European Health Insurance Card is dead handy, providing access to healthcare for EU residents while travelling in Europe -- it's definitely worth having one.

There were a few reports in the Irish newspapers last week of an announcement by the Health Service Executive, warning of "a bogus website" which charges a fee of EUR22 to process applications for this:

The HSE also warned that the site is asking applicants to submit detailed financial information. "It has come to the attention of the Health Service Executive that Irish residents are being targeted by a website which is unnecessarily charging people to apply for EHIC cards. The bogus site concerned -- http://www.ehic-card.eu/ -- is not connected to the HSE," said the HSE in a statement.

I'd link to the HSE's press release on the topic, but it's down, apparently -- and that's pretty indicative of the problem. You see, I've been trying to apply for one of these recently.

The HSE has been announcing that there's no need to use this "bogus site", since we can just use the "real" site at http://www.ehic.ie/ to apply for one. Here's what they neglect to mention:

  • (a) that unless you're a pensioner you can't apply for one online -- you have to print out a form, fill it in, and post it to your local health office.
  • (b) there's no indication on the site as to what exactly your "Local Health Office" may be, just a long list of mysterious locations.
  • (c) in order to apply, the form demands that you supply all that 'detailed financial information' -- namely your name, address, date of birth, proof of residency, and PPS number -- anyway.
  • (d) the "bogus site" isn't really all that bogus after all.

If they had a simple and usable online application process, perhaps they wouldn't be plagued by other sites attempting to offer that service for what is really a quite reasonable EUR22 fee?

This is a pretty frequent phenomenon on Irish governmental websites; a half-assed attempt to bring governmental services online, resulting in shiny informational sites, full of clip-art of smiling people talking on the phone, which all come down to a bottom line of "print this out and post it in" or "call this number" -- business as usual. Having said that, at least I can generally still get a human on the phone, which still beats dealing with US government agencies, I guess!

BTW, I notice the HSE claim that it only takes 10 working days for an EHIC to arrive using their system. I applied for mine 3 weeks ago, and there's been no word yet...

ehic eu government health hse internet ireland

Don't use bl.spamcop.net as a blocklist

Update: as of Oct 2007, this advice is obsolete. The Spamcop algorithms have been greatly improved, as far as I and others can tell.

I've been hearing increasing reports of false positives using bl.spamcop.net.

One today spurred me to check out exactly how many times it I'm seeing it misfiring on nonspam in my own mail collection. The results have been pretty astonishing.

In my nonspam collection, it fired on 1043 messages out of 8415 in July; 12.4% of the mail. It gets worse for August, though -- 884 messages out of 3729 since the start of August. That's a staggering 23% of my nonspam mail this month. ;)

Most of that is due to the listings of GMail and Yahoo! Groups, both of which seem to have been listed for large swathes of the past month and a half.

Now, an important point -- it can work pretty well as a single input to a scoring system, like Spamcop itself or SpamAssassin. In fact, I didn't lose any mail as a result of those listings; SpamAssassin assigns only 1.5 points to the RCVD_IN_BL_SPAMCOP_NET rule, so it's easily corrected by other rules.

However, people using it to block or reject spam outright, or who've changed the score of the RCVD_IN_BL_SPAMCOP_NET rule, need to turn that off ASAP -- as they are losing mail.

anti-spam blocklists dnsbls smtp spamcop

More parallel string-match algorithm hacking: re2xs

Last week, Matt Sergeant released a great little perl script, re2xs, which takes a set of simplified regexps, converts them to the subset of regular expression language supported by re2c, then uses that to build an XS module.

In other words, it offers the chance for SpamAssassin rules to be compiled into a trie structure in C code to match multiple patterns in parallel. Given that this is then compiled down to native machine code, it has the potential to be the fastest method possible, apart from using dedicated hardware co-processors.

Sure enough, Matt's results were pretty good -- he says, 'I managed to match 10k regexps against 10k strings in 0.3s with it, which I think is fairly good.' ;)

Unfortunately, turning this into something that works with SpamAssassin hasn't been quite so easy. SpamAssassin rules are free to use the full perl regular expression language -- and this language supports many features that re2c's subset does not. So we need to extract/translate the rule regexps to simplified subsets. This has generally been the case with all parallel matching systems, anyway, so that's not a massive problem.

More problematically, re2c itself does not support nested patterns -- if one token is contained within another, e.g. "FOO" within "FOOD", then the subsumed token will not be listed as a match. SpamAssassin rules, of course, are free to overlap or subsume each other, so an automated way to detect this is required.

For simple text patterns, this is easy enough to do using substring matching -- e.g. "FOOD" =~ /\QFOO\E/ . Unfortunately, once any kind of sophisticated regexp functionality is available, this is no longer the case: consider /FOO*OD/ vs /FOO/ , /F[A-Z]OD/ vs /FO[M-P]/ , /F(?:OO|U)D/ vs /F(?:O|UU)?O/ .

The only way to do this is to either (a) fully parse the regexp, build the trie, and basically reimplement most of re2c to do this in advance; or (b) change the trie-generation code in re2c to support states returning multiple patterns, as Aho-Corasick does.

I requested support for this in re2c, but got a brush-off, unfortunately. So work continues...

In other news, that food poisoning thing I had back at the end of June has lingered on. It's now pretty clear that it isn't food poisoning or a stomach bug... but I still have no idea what it actually is. No fun :(

aho-corasick matt-sergeant perl re2c regexps spamassassin strings tries

"Stretch-to-fit Textareas" Greasemonkey User Script

Here's another quick-hack Greasemonkey user script I wrote recently.

Stretch-to-fit Textareas is a user script which improves the usability of editable textareas; it causes them to "stretch" vertically to fit their contents, as you type. This behaviour was inspired by that of textareas in FogBugz.

It can be inhibited by turning off the small checkbox to the right of each textarea.

Update: it's worth noting that this is different from the Resizeable Textareas Firefox extension. Whereas the latter allows the user to resize the textareas by hand, this user script does that action automatically, based on the contents of the field; no manual resize-handle-searching and dragging is required. On the other hand, this user script will only stretch textareas vertically, whereas the extension allows them to be dragged in both dimensions. In fact, the two are complementary -- I'm running both, and I suggest you do too ;)

Update 2: here's a Firefox extension version -- Greasemonkey not required!

greasemonkey hacks html javascript software textareas ui user-scripts

LKML discusses anti-spam moderation

LKML: Alexey Zaytsev: Time to forbid non-subscribers from posting to the list? -- the linux-kernel mailing list discusses list moderation as an anti-spam strategy.

Spam really sucks; anything that deals with email now has to include some set of anti-spam features because of it. The LKML has important features that mitigate against simply closing the list partially, such as being a point where bug reports are submitted -- so this is a thorny issue for them.

For what it's worth, I have written a system to further automate moderation beyond the basic features provided by Mailman and ezmlm. http://taint.org/wk/ModerateList describes this in detail; in essence, it's a specialised mail user agent designed to moderate lists quickly and efficiently, with an outboard spam filter built in (SpamAssassin, of course, via its perl API).

I moderate about a thousand messages per week using this (last time I checked), and it takes about 30 seconds per day to do so, so it's pretty efficient.

In other news: wow, talking to a good accountant can really mitigate complicated tax issues... phew.

anti-spam spamassassin smtp

Wedding Poems

OK -- looks like I've found the perfect poem for our wedding ceremony; allow me to present "Gravity of Love":

One day, one day I asked myself
What is the right number or symbol?
What is the perfect equation?
What truly is LOGIC?
And who decides right reasoning?

In cause of no answer to my quest,
I traveled through the physical and metaphysical,
I traveled through the delusional and mystical
And at last back to the physical.

I made most important invention of my life career
That it's only in the mysterious equation; logic of love
Any logical; mystical and psychological reasoning can be found.
It's you in me I only believe that's true and real

All I can say is -- Wow.

funny poetry vogon weddings wol

Underwhelmed by ScreenClick

For the past few years, I've been a very happy user of Netflix, the innovative web site which let you receive DVDs via the post for a flat fee per month, for US residents. When I got back to Dublin, I was very happy to see that there was a local equivalent, in the form of ScreenClick -- so I signed up.

However, I've become increasingly disillusioned with their service, for the same reasons as Adrian Weckler writes about here...

Turnaround time: this varies wildly, and can take nearly a week to turn around a DVD from dropping it in the postbox to receiving the next one. Netflix was reliably two days for me, out in suburban Orange County, California; Even this Kansas blogger noted that the longest they'd waited was 4 days.

This may seem to be an externality for Screenclick -- but really, it shouldn't be. Their business is built on the postal service, and they have to have decent results for it to work.

The 'wishlist' model: Netflix uses a queue, operating on a first-in, first-out model, while Screenclick uses something they call a 'wishlist', where the DVDs are delivered based both on position in the list and availability -- in other words, you can find you've been delivered the DVD at number 10 in your list, instead of whatever's at the top.

Again, superficially a minor point. However, one important factor is that these services are bought by households, not by individuals. Chez jm, that means that we operated a pretty strict alternating system in our Netflix queue -- one movie for me, one movie for the lovely C, repeat. This is now thoroughly scuppered with a random 'lucky dip' system. On top of that, forget about watching a serial in order. The end result is a mess.

The website: it's atrocious, a hodge-podge of ads for third-party sites, press coverage of Screenclick, more ads for Screenclick (hey, I'm already a customer!), and news clippings I couldn't care less about -- with finally a few tiny sidebar boxes containing the things I want (login, search box and wishlist). My impression: it's designed to sell the company to investors and advertisers, not for customer use.

On top of that, it's all squished into a tiny window -- Irish web designers need to buy bigger screens! That late-'90's Jakob Nielsen thing about users not knowing how to scroll? They've learned by now.

That's not even talking about the awful Javascript that's used to edit the wishlist ordering, where little buttons need to be clicked repetitively, one by one, to reorder the list. Surely someone took a look around at other sites first -- Amazon perhaps -- to see how other sites do it?

Anyway, on this count, I sent in a mail containing a batch of bug reports and unsolicited opinions, and got no reply. ;)

Less bang-for-buck: pretty simple. Netflix: 3 movies at a time, more movies in the collection, $17.99 per month; Screenclick, 2 movies at a time, EUR 19.99 ($25.56, $10 more expensive than the equivalent Netflix service) per month. Surprisingly, this is actually a minor issue compared to the others, though, since it's made plain from the outset.

These may seem to be minor points, but when selling a disposable-income service to consumers, the difference between an essential leisure-time service and a waste of pocket money is a very fine line. Looks like Adrian eventually cancelled. I'm not at that point yet, but it's heading that way...

b2c dvd ireland netflix screenclick video

What Jeff Killed

What Jeff Killed is a blog from Shadow Hills, CA, documenting the murderous antics of Jeff, a large ginger tomcat:

we provide Jeff with food and water; however, this does little to lessen his killer instinct. To humans, Jeff is an exceptionally good-tempered and friendly cat; to rodents and other small animals, he is death itself. It could be that Jeff likes to bring us gifts to repay our hospitality. Perhaps he is simply a hardwired killing machine. All we know for certain is that he hunts down a wide variety of small animals and disembowels, decapitates, and dines on them. Often.

This was passed on by the lovely C, who noted 'number of kills is about the same, cat for cat' -- indeed, Bubba, our cat, certainly had a similar career in Irvine, CA. However, I notice that as yet, there are no cases where Jeff has left the entrails and decapitated head of a rabbit lying up against the sandals of the neighbour's 6 year old daughter... that was fun.

animals bubba cats gore nature pets wildlife

Kick.ie

I just noticed an interesting new site on the Irish web -- kick.ie.

It's closely based on the model of Digg, with a community of contributors who post new stories, comment, and "kick" stories they like so that those stories are given top billing. The interesting twist is that it's not as general as Digg -- instead of having a very broad "news" site, covering all bases, there are instead a smaller set of topic-focused "kick" sites. Using this model for the relatively-small Irish weblogging scene works pretty well, I think.

It's nicely done -- fast, clean, and featuring nifty features like RSS feeds throughout, and reader-contributed tagging. Nice work by Gavin Joyce!

Well worth subscribing to.

(Also, it's cool to see that one of my posts discussing Irish road deaths managed to mass 7 'kicks' a couple of weeks back ;)

community ireland irishblogs kick.ie

Year 2038 Bug Strikes Early

Noted previously in the link-blog -- here are more details on the first known instance of the Year 2038 UNIX epoch rollover bug, where AOLServer installs hung due to a 32-year timeout value hitting the end-of-epoch.

It appears that it was caused by an 'official workaround' for an Oracle driver bug, where an infinite timeout was desired. Instead of implementing true support for infinite timeouts, the developer just used a very large value -- one BILLION seconds, Dr. Evil-style. Unfortunately, this led to the overflow issue.

Here's some key snippets from the mailing list thread:

Bas Scheffers:

On 17 May 2006, at 21:34, Dossy Shiobara wrote:

Dave Siktberg seems to have narrowed it down to 2006-05-12 21:25.

In what timezone? It sound like that could equate to "Sat May 13 02:27:28 BST 2006", or 1147483648 seconds since epoch, which makes it exactly 1,000,000,000 seconds until expiry of 32 bit time. Coincidence? Seems too strange as to a computer that is not a nice round number.

'Jesus' Jeff Rogers:

I had problems starting at the exact same time but on Solaris, where they manifested as a EINVAL return from pthread_cond_tomedwait. After a day of tracing the problem with debug builds and working with my sysadmin to track what changed (of course, nothing had) I cam to the same 1 billion second issue.

Which coincidentally is the expiry time (MaxOpen and MaxIdle) set on my database connections. My system is ACS-derived, so I wouldn't be surprised if these database settings are common in other ACS-derived systems.

The only bug is that Ns_CondTimedWait doesn't do any wraparound on the time parameter. All the same, I've been enjoying telling people that I hit my first y2038 bug.

Andrew Piskorski:

For those interested in ancient trivia, I think it was TWO bugs, one in the Oracle driver and/or OCI libraries (most likely OCI), and one in AOLserver. I think the workaround dates from before I ever used AOLserver, but I have these old comments in my AOLserver config file:

MaxIdle and MaxOpen:

Settings these to 1000000000 is a historical bug workaround. Could now probably set this to some normal number, or set to 0 to disable entirely. E.g., in this thread Rob Mayoff says:

http://www.arsdigita.com/bboard/q-and-a-fetch-msg?msg%5fid=000Ibq

It is a bug workaround. Many Linux users (including me) saw that when AOLserver tried to close a database connection, it would hang in the Oracle driver. So people started setting and MaxIdle to a very large number to keep connections from closing. You can also set them to zero, but at the time the bug was discovered, AOLserver had a bug that prevented you from setting them to zero.

I believe the bug was also seen, very rarely, on Solaris.

Curtis Galloway managed to get Oracle to investigate. They suggested to workarounds: use IPC or TCP to connect (which is what I do on my system), or set bequeath_detach=yes in sqlnet.ora.

2002/01/10 14:22 EST

Uselessly, the arsdigita thread URL is now a victim of needless website reorganisation, and redirects to their front page. Still, I think that's enough info.

This is certainly going to be one of the first widely-recorded Y2038 rollover bugs, I think...

aolserver bugs epoch timeouts unix y2038

A Little Downtime

Quick note: taint.org, and the other sites on the same host, will be down for somewhere between 30 minutes and an hour tomorrow, at 1000 UTC, as the host moves to a new datacenter (and a new IP address).

Handily, the host will also get a hefty RAM upgrade, which should improve matters the next time we get slashdotted ;)

(If you need to get in touch during the downtime, jmason at gmail dot com will be the best bet.)

Update: this is now complete.

downtime meta server

'Small Engine Repair'

Last Friday, I visited the Galway Film Fleadh to see the Irish premiere of a new feature-length movie called Small Engine Repair, which was directed by a mate of mine called Niall Heery.

I loved it -- funny, extremely black comedy, reminded me a lot of The Deer Hunter in visual style, but unmistakably Irish at the same time. (Blog movie reviews seem to be out of favour right now, so I'll leave it at that.)

Here's hoping it picks up wider distribution very soon -- it deserves to be big, I think. Nice one, Niall! Happily, the voters of the Fleadh agreed -- it went on to win the Best First Feature award.

Actually, it's been a good year for friends and family at the Fleadh -- I note that my cousin, Eoin Ryan, picked up first prize for Best Irish Short Animation with his excellent short, Demon. cool!

awards demon eoin-ryan family films fleadh friends galway movies niall-heery small-engine-repair

Road Deaths in Ireland

Road deaths are a hot topic in Ireland. They're actually lower, per capita, than rates in other countries, but are given plenty of column inches and headlines here, and have become a government priority as a result.

Here's the latest headline:

[Gay Byrne, head of the Road Safety Authority] claimed young people were ignoring road safety campaigns and that all he could do was to warn people to reduce speed and not to drink and drive. "I don't know what else we can do. We have done all the horror ads, but there are obviously a great number of people who don't look at television, listen to radio, or read newspapers and don't get the message," he said.

Ads. Great. Well, one thing that could be done is fixing the unsafe roads, and building decent ones; Irish country roads, while picturesque, are unable to deal with the levels of traffic they're now facing. It's time to apply modern safety standards, instead of considering a 2-lane boreen to be adequate.

There's been a bit of improvement here; the roads from Dublin to Sligo, and from Dublin to Dundalk, for example, are both now fantastic, well-designed roads, and safe as a result. But try to get from Sligo to anywhere that isn't Dublin, and you're right back on those boreens again -- with maniacs overtaking on blind corners into oncoming traffic and so on.

But here's the real reason for the post. I have to reserve some special scorn for this idiot:

Hotelier Declan Corbett, who employed both siblings, yesterday called on Mr Byrne to resign following his comments.

"I am after coming down from the Frewen family house and if Gay Byrne or Michael McDowell were after witnessing what I saw he wouldn't be coming out this morning with this ranting and blaming the young people of Ireland," he said. [...]

"Gay Byrne was given this job and he shouldn't have been given this job. It's typical Dublin 4 job-for-the-boys. A job like this should be given to someone in rural Ireland - somebody like Sean Og O'hAilpin that young people look up to."

Sean Og O'hAilpin, eh? As Paul Moloney noted -- that'd be the same Sean Og who ended his Gaelic football career when he overtook a car on a bend, at speed, crashing head-on into oncoming traffic? A great example, indeed.

I think that might be the problem.

ireland politics road-deaths road-safety safety sport

A Released Perl With Trie-based Regexps!

Good news! From the Perl 5.9.2 'perl592delta' change log:

The regexp engine now implements the trie optimization : it's able to factorize common prefixes and suffixes in regular expressions. A new special variable, ${^RE_TRIE_MAXBUF}, has been added to fine-tune this optimization.

in other words, the trie-optimization patch contributed by demerphq back in March 2005 is now in a released build of Perl. Yay!

Here's a writeup of what it does:

A trie is a way of storing keys in a tree structure where the branching logic is determined by the value of the digits of the key. Ie: if we have "car", "cart", "carp", "call", "cull" and "cars" we can build a trie like this:

        c + a + r + t
          |   |   |
          |   |   + p
          |   |   |
          |   |   + s
          |   | 
          |   + l - l
          |   
          + u - l - l

What the patch does is make /a | list | of | words/ into a trie that matches those words. This means that we can efficiently tell if any of the words are at a given location in a strng by simply walking the string and trie at the same time. In many cases we can rule out the entire list by looking at only one character of the input. The current way perl handles this would require looking at N chars where N is the number of words involved. (BTW: Thats the beauty of a trie, its lookup time is independent of the number of words it stores but rather on the key length of the word being looked up. )

SpamAssassin is, of course, both (a) very regular-expression-intensive and (b) searches a single block of text for a large number of independent patterns in parallel. I'd love to see someone coming up with a patch to SpamAssassin that uses trie-compatible regexps when the perl version is >= 5.9.2, and gets increased performance that way. hint ;)

BTW, the Regexp::Trie module on CPAN is related -- in that it, similar to Regexp::Optimizer, Regex::PreSuf, or Regexp::Assemble, will compile a list of words or regular expressions into a super-efficient trie-style regexp. However, without the trie patch to the regexp engine itself, this would be a minor efficiency tweak at best; although having said that, Regexp::Assemble's POD notes:

You should realise that large numbers of alternations are processed in perl's regular expression engine in O(n) time, not O(1). If you are still having performance problems, you should look at using a trie. Note that Perl's own regular expression engine will implement trie optimisations in perl 5.10 (they are already available in perl 5.9.3 if you want to try them out). Regexp::Assemble will do the right thing when it knows it's running on a a trie'd perl. (At least in some version after this one).

(PS: interestingly, demerphq mentioned back in March 2005 that he was working on Aho-Corasick matching next. A-C is a great parallel-matching algorithm, and I would imagine it would increase performance yet more. I wonder what happened to that...)

aho-corasick coding matching perl software tries

Linksys NSLU2 Contemplation

These days, I shouldn't have time for after-hours hobby projects; I should be organising weddings and so on. But it's a compulsion. ;)

As a result, here's some notes I've been keeping on building a home NAS (network-attached storage) server, using the nifty little Linksys NSLU2: http://taint.org/wk/BuildingNasServer

Anyone done this? Care to leave a comment noting the results? I'm curious.

hacking hobby linksys nas nslu2 toys

Smithfield's Decay

I live in Dublin 7, on the north side of Dublin. Historically, the north side has been run-down and under-developed, always losing out to the more well-maintained, and well-funded, south side.

A few years ago, though, it looked like this was changing; the Spire in O'Connell St. was erected, new bars and shops opened, and the Luas line was installed. One site, Smithfield Square in Dublin 7, was radically overhauled; its derelict buildings were renovated or knocked down, new construction was going up, and fantastic architecture was being put in place. The future was looking bright.

That was back around 2000/2001; in fact, I remember walking past the avenue of braziers on Milennium night. Fast forward -- I've been back in Dublin 6 months now, and as far as I can tell, all that has petered out, while I was away. This Frank McDonald article in the Irish Times sums it up perfectly:

The cafes, bars and restaurants that were meant to be part of [Smithfield] are nowhere to be seen. The promoters had promised residents "an entire lifestyle on your doorstep, extended by the possibilities of the city and beyond". There was to be an eclectic mix of restaurants and stylish bars - "a unique mix of offerings, ranging from food to culture to entertainment and leisure in a family-friendly development", according to Paddy Kelly.

In November 2003, his son Chris said: "We are hoping it will emulate the New York example where everything - from your launderette, hairdresser and your masseuse - is only a block away, and that people will live, work and socialise within the same area". On another occasion, London's Covent Garden was cited as the urban model.

Incredibly, the lower end of Smithfield - through which Luas runs - remains unfinished six years after the rest of it was re-paved in an award-winning scheme by McGarry Ni Eanaigh Architects. It also has a redundant stone-clad structure, which served briefly as a plug-in point for open-air concerts.

The only real entertainment available in the area is the annual Christmas ice rink or the seriously indigenous and pre-existing horse fair, still being held on the first Sunday of every month.

Otherwise, the plaza attracts an assortment of winos, or juvenile offenders on their way to the Children's Court, handcuffed to prison warders.

The little stage set up for open-air concerts is now covered in graffiti, and hosts a solid crew of junkies and winos; the braziers are no longer lit; the square boasts a permanent encrustation of construction fencing. The fruit and veg market that used to be held in one of the buildings has been bought out and moved on to somewhere on the outskirts of town, replaced by "Fresh", which -- while it sells the odd bit of interesting food, like the nice Bretzel bakery bread -- is really just an upscale Spar. Even the local Indian takeaway has dropped in quality, and is now shipping out generic dishes that aren't even made with Indian spices.

To be quite honest, Smithfield -- and, to be honest, much of the north side -- gives the impression it's been abandoned again, after only one or two years of short-term investment, and no long-term thinking.

What happened?

(PS: it's not over for Dublin 7, though -- about a half-mile from Smithfield, a flashy new restaurant is set to open this weekend. But who's to say that Capel St. won't find itself similarly forgotten in a year or two?)

dublin ireland history

Blogorrah

Blurred Keys: Blogorrah.com - the start of empire building with 'very few overheads'. Blurred Keys, "an Irish media blog", brings the revelation that Blogorrah "copies" Gawker.com.

Honestly, though, this is blatantly obvious -- and I'd consider it unfair to call this "copying". It's simply taking a successful format and adapting it to the local market, and doing so very well indeed if you ask me.

Blogorrah is a hilarious read. If you're Irish and you're not subscribed, you're really missing out... it's the funniest thing on the Irish web these days.

blogorrah dublin funny ireland weblogs

Daily Links Posting Off Again

I've turned this off again; even though it provides a nice way for people to comment and discuss link posts (which del.icio.us doesn't provide, unfortunately), it does tend to break up the flow of the "main" article part of the weblog, and isn't entirely popular I think.

If you're interested in the links, your best bet is to read either the main page itself in your browser, where the link-blog appears over there ---> , or one of these RSS feeds:

blogs aggregation Links delicious link-blogs rss blogging

links for 2006-07-04

links for 2006-07-03

links for 2006-07-02

Ecch - that must have been poisonous! --more--

Since consuming a misjudged sossie at a BBQ last Saturday, I've been suffering from a stomach bug, causing nausea, sweating and the occasional vomit (never fun). On top of this, I spent Monday to Wednesday in Serbia on a work trip.

The result -- I've managed to miss the entirety of ApacheCon EU 2006 in Dublin. I considered dropping down to catch the end of it this morning, but had to abort the attempt due to a bout of in-transit nausea.

All in all, a pretty miserable week. :(

Update: here's something vaguely uplifting -- a cover of Europe's 'Final Countdown' in Khmer.

Update 2: wow, that little stomach bug has been wreaking havoc -- over the weekend 3 more people laid low in our social group. sorry all...

apachecon food-poisoning illness mind-the-sausages

links for 2006-06-29

links for 2006-06-27

links for 2006-06-21

links for 2006-06-20

links for 2006-06-19

Vodafone Ireland's flat rate mobile data card

Adrian Weckler posts details of Vodafone Ireland's new flat price datacard; costing 50 Euros per month, including VAT; fully flat rate (hooray, something useful at last!); and they claim that they'll be rolling out HSDPA, which offers 1.2Mbps to 11Mbps rates, 'starting in Dublin in October'.

Those are great numbers, but further info seems thin on the ground; they haven't bothered updating their own website yet, amazingly.

Anyone got further info? What rates does it offer right now? How would one order such a beast?

3g dublin hsdpa ireland mobile vodafone

Holidaze

Quick note -- I'm off on vacation next week -- so I probably won't read any email while I'm there ;) Talk to you after the 17th.

fun holidays life meta vacation

links for 2006-06-07

Running Dapper

I took the plunge over the weekend, and live-upgraded the new 'Dapper Drake' Ubuntu release -- ouch. Here's the two key lessons I learned:

  • Don't run "grub-install" in a misremembered attempt to update the current GRUB boot menu 'menu.lst' file with the new kernel; sadly, this will quietly remove important details from your old menu.lst, such as "initrd" lines, rendering those kernels unbootable. Moral: ensure brain is in gear before meddling with MBRs!

  • If you're a Kubuntu user, watch out. Ensure you run apt-get install ubuntu-base ubuntu-desktop -- bringing the entirety of GNOME up to date -- as well as apt-get install kubuntu-desktop after the upgrade; it appears that some part of a new hotplugging subsystem is not included as a dependency of kubuntu-desktop. Failure to do this results in an inability to use USB/hotpluggable devices, including internal devices like the Synaptics touchpad. No pointer devices (mice or touchpads) means no X server at boot, which is always a little annoying.

Some day I'll just do things the right way, and do a fresh-from-CD install instead. Ah well. The good stuff: the new kernel, or possibly Xorg, is proving to be a lot speedier -- window updates are noticeably smoother; and the new Ubuntu GNOME theme is similarly tasty.

dapper gnome grub kde kubuntu linux software ubuntu upgrades

SpamAssassin advisory CVE-2006-2447

CVE 2006-2447, in which Radoslaw Zielinski spotted a nasty in spamd's 'vpopmail' support in pretty much all recent versions of Apache SpamAssassin.

If you use spamd with vpopmail, go read the advisory and determine if you need to take action. Not many people will need to, I think; it's a very rare setup. Still, it's important to get the warning out there anyway.

The irony is that the bug is triggered partly by the "--paranoid" switch. This was intended to increase security, by increasing paranoia when possibly-unsafe situations arose -- hence providing a great demonstration of how the addition of optional code paths, even in the best intentions, can reduce security by allowing bugs to creep in unnoticed.

bugs exploits security spamassassin vpopmail

links for 2006-06-06

Web x, where x != 2.0

Regarding the O'Reilly/CMP "Web 2.0 (SM)" trademark shitstorm, Sean McGrath humourously suggested a workaround -- using a different revision number instead of "2.0", specifically e, 2.71....

However, it's not quite that simple in many jurisdictions, apparently. It seems that trademark law -- in the US, at least -- allows trademarks which include a number to also cover uses within roughly plus or minus 10 of that number. In other words, CMP's application will cover the range from Web -8.0 (SM) (assuming negative numbers are included?) to Web 12.0 (SM).

So much for "Web 3.0", "Web 2.1", "Web 2.71...", and so on. Back to the drawing board, Sean! ;)

(disclaimer: IANAL, of course. Credit to Craig for that tidbit.)

Update: doh, got the value of e wrong...

cmp e ip oreilly trademarks us-law web2.0

links for 2006-06-01

links for 2006-05-31

Blog Spam, and a 'nofollow' Post-Mortem

An interesting article on blog-spam countermeasures -- Google's embarrassing mistake. Quote:

I think it's time we all agreed that the 'nofollow' tag has been a complete failure.

For those of you new to the concept, nofollow is a tag that blogs can add to hyperlinks in blog comments. The tag tells Google not to use that link in calculating the PageRank for the linked site. [...]

Since its enthusiastic adoption a year and a half ago, by Google, Six Apart, Wordpress, and of course the eminent Dave Winer, I think we can all agree that nofollow has done -- nothing. Comment spam? Thicker than ever. It's had absolutely no effect on the volume of spam. That's probably because comment spammers don't give a crap, because the marginal cost of spamming is so low. Also, nofollow-tagged links are still links, which means that humans can still click on them -- and if humans can click, there's a chance somebody might visit the linked sites after all.

I agree. At the time, I pointed at this comment from Mark Pilgrim:

Spammers have it in their heads now that weblog comments are a vector to exploit. They don't look at individual results and tweak their software to stop bothering individuals. They write generic software that works with millions of sites and goes after them en masse. So you would end up with just as much spam, it would just be displayed with unlinked URLs.

Spammers don't read blogs; they just write to them.

I still think he was spot on.

However, one part of the 'Google's embarrassing mistake' article is a red herring -- I think the chilling effect on "nonspam links" is not to be worried about; as Jeremy Zawodny said, life's too short to worry about dropping links purely in the hopes of giving yourself Page Rank. I don't know if I really want links that people are leaving purely for that reason. ;)

In fact, I wouldn't be surprised to hear that Google's crawler starts treating "nofollow" links as mildly non-spammy in a future revision, due to their wide use in wikis, blogs etc.

To be honest, though -- I don't see the problem of blog-spam much anymore. As I said here:

[Weblog] comment spam should be a lot easier to deal with than SMTP spam. ... With weblog comments, you control the protocol entirely, whereas with SMTP you're stuck with an existing protocol and very little "wiggle room".

On my WordPress weblog [ie. here] -- which, admittedly, gets only about 1/4 of the traffic plasticbag.org does -- I've instituted a very simple check stolen from Jeremy Zawodny. I simply include a form field which asks the comment poster for my first name, and if they fail to supply that, the comment is dropped. In addition, I've removed the form fields to post directly, requiring that all comments are previewed; this has the nice bonus of increasing comment quality, too.

Those are the only antispam measures I'm using there, and as a result of those two I get about 1 successful spam posted per week, which is a one-click moderation task in my email. That's it.

The key is to not use the same measures as everyone else -- if every weblog has a different set of protocols, with different form fields asking different simple questions, the only spammers that can beat that are the ones that write custom code for your site -- or use human operators sitting down to an IE window.

Trackbacks, however -- turn that off. The protocol was designed poorly, with insufficient thought given to its abuse potential; there's no point keeping it around, now that it's a spam vector.

Finally, a "perfect" solution to blog spam, while allowing comments, is unachievable. There will always be one guy who's going to sit down at a real web browser to hand-type a comment extolling the virtues of some product or another. The goal is to get it to a level where you get one of those per week, and it's a one-click operation to discard them.

(Update: This story got Slashdotted! The poor server's been up and down repeatedly -- looks like it needs an upgrade. In the meantime, WP-Cache has proven its weight in gold; recommended...)

antispam blog-spam nofollow spam weblogs

Retroactive Tagging With TagThe.Net

Hacky hack hack.

Ever since I enabled tags on taint.org, I've been mildly annoyed by the fact that there were thousands of older entries deprived of their folksonomic chunky goodness. A way to 'retroactively tag' those entries somehow would be cool.

Last week, Leonard posted a link on his linkblog to TagThe.net, a web service which offers a nifty REST API; simply upload a chunk of text, and it'll suggest a few tags for that text, like this:

echo 'Hi there, I am a tag-suggesting robot' | curl "http://tagthe.net/api/?text=`urlencode`"
<?xml version="1.0" encoding="UTF-8"?>
<memes>
  <meme source="urn:memanage:BAD542FA4948D12800AA92A7FAD420A1" updated="Tue May 30 20:20:39 CEST 2006">
    <dim type="topic">
      <item>robot</item>
    </dim>
    <dim type="language">
      <item>english</item>
    </dim>
  </meme>
</memes>

This looked promising.

Anyway, I've now implemented this -- it worked great! If you're curious, here's details of how I did it. It's a bit hacky, since I'm only going to be doing this once -- and very UNIXy and perlish, because that's how I do these things -- but maybe somebody will find it useful.

How I Retroactively Tagged taint.org

This weblog runs WordPress -- so all the entries are stored in a MySQL database. I took the MySQL dump of the tables, and a quick script figured out that out of somewhere over 1600-ish posts, there were 1352 that came from the pre-tag era, requiring tag inference. A mail to the TagThe.Net team established that they were happy with this level of usage.

I grepped the post IDs and text out of the SQL dump, threw those into a text file using the simple format 'id=NNN text=SQLHTMLSTRING' (where SQLHTMLSTRING was the nicely-escaped HTML text taken directly from the SQL dump), and ran them through this script.

That rendered the first 2k of each of those entries as a URL-encoded string, invoked the REST API with that, got the XML output, and extracted the tags into another UNIXy text-format output file. (It also added one tag for the 'proto-tag' system I used in the early days, where the first word of the entry was a single tag-style category name.)

Next, I ran this script, which in turn took that intermediate output and converted it to valid PHP code, like so:

cat suggestedtags | ./taglist-to-php.pl  > addtags.php
scp addtags.php my.server:taint.org/wp-admin/

The generated page 'addtags.php' looks like this:

<?php
  require_once('admin.php');
  global $utw;
  $utw->SaveTags(997, array("music","all","audio","drm-free",
      "faq","lunchbox","destination","download","premiere","quote"));
  [...]
  $utw->SaveTags(998, array("software","foo","swf","tin","vnc"));
  $utw->SaveTags(999, array("oses","eek","longhorn","ram",
    "winsupersite","windows","amount","base","dog","preview","system"));
?>

Once that page was in place, I just visited it in my (already logged in) web browser window, at http://taint.org/wp-admin/addtags.php, and watched as it gronked for a while. Eventually it stopped, and all those entries had been tagged. (If I wasn't so hackish, I might have put in a little UI text here -- but I didn't.)

The results are very good, I think.

A success: http://taint.org/tag/research has picked up a lot of the interesting older entries where I discussed things like IBM's Tieresias pattern-recognition algorithm. That's spot on.

A minor downside: it's not so good at nouns. This entry talks about Silicon Valley and geographical insularity, and mentions "Silicon Valley" prominently -- one or both of those words would seem to be a good thing to tag with, but it missed them.

Still, that's a minor issue -- the tags it has suggested are generally very appropriate and useful.

Next, I need to find a way to auto-generate titles for the really old entries ;)

archives hacks meta tagging tags tagthe.net weblog

links for 2006-05-29

Web 2.0 and Open Source

A commenter at this post on Colm MacCarthaigh's weblog writes:

I guess I still don't understand how Open Source makes sense for the developers, economically. I understand how it makes sense for adapters like me, who take an app like Xoops or Gecko and customize it gently for a contract. Saves me hundreds of hours of labour. The down side of this is that the whole software industry is seeing a good deal of undercutting aimed at sales to small and medium sized commercial institutions.

Similarly, in the follow-up to the O'Reilly "web 2.0" trademark shitstorm, there's been quite a few comments along the lines of "it's all hype anyway".

I disagree with that assertion -- and Joe Drumgoole has posted a great list of key Web 2.0 vs Web 1.0 differentiators, which nails down some key ideas about the new concepts, in a clear set of one-liners.

Both open source software companies, and "web 2.0" companies, are based on new economic ideas about software and the internet. There's still quite a lot of confusion, fear and doubt about both, I think.

Open Source

As I said in my comment at Colm's weblog -- open source is a network effect. If you think of the software market as a single buyer and seller, with the seller producing software and selling to the buyer, it doesn't make sense.

But that's not the real picture of a software market. If you expand the picture beyond that, to a more realistic picture of a larger community of all sorts of people at all levels, with various levels interacting in a more complex maze of conversation and transactions, open source creates new opportunities.

Here's one example, speaking from experience. As the developer of SpamAssassin, open source made sense for me because I could never compete with the big companies any other way.

If I had been considering it in terms of me (the seller) and a single customer (the buyer), economically I could make a case of 'proprietary SpamAssassin' being a viable situation -- but that's not the real situation; in reality there was me, the buyer, a few 800lb gorillas who could stomp all over any puny little underfunded Irish company I could put together, and quite a few other very smart people, who I could never afford to employ, who were happy to help out on 'open-source SpamAssassin' for free.

Given this picture, I'm quite sure that I made the right choice by open sourcing my code. Since then, I've basically had a career in SpamAssassin. In other words my open source product allowed me to make income that I wouldn't have had, any other way.

It's certainly not simple economics, is a risk, and is complicated, and many people don't believe it works -- but it's viable as an economic strategy for developers, in my experience. (I'm not sure how to make it work for an entire company, mind you, but for single developers it's entirely viable.)

Web 2.0

Similarly -- I feel some of the companies that have been tagged as "web 2.0" are using the core ideas of open source code, and applying them in other ways.

Consider Threadless, which encourages designers to make their designs available, essentially for free -- the designer doesn't get paid when their tee shirt is printed; they get entered into a contest to win prizes.

Or Upcoming.org, where event tracking is entirely user-contributed; there's no professional content writers scribbling reviews and leader text, just random people doing the same. For fun, wtf!

Or Flickr, where users upload their photos for free to create the social experience that is the site's unique selling point.

In other words -- these companies rely heavily on communities (or more correctly certain actors within the community) to produce part of the system -- exactly as open source development relies on bottom-up community contribution to help out a little in places.

The alternative is the traditional, "web 1.0" style; it's where you're Bill Gates in the late 90's, running a commercial software company from the top down.

  • You have the "crown jewels" -- your source code -- and the "users" don't get to see it; they just "use".
  • Then they get to pay for upgrades to the next version.
  • If you deal with users, it's via your sales "channels" and your tech support call centre.
  • User forums are certainly not to be encouraged, since it could be a PR nightmare if your users start getting together and talking about how buggy your products are.
  • Developers (er, I mean "engineers") similarly can't go talking to customers on those forums, since they'll get distracted and give away competitive advantage by accidentally leaking secrets.
  • Anyway, the best PR is the stuff that your PR staff put out -- if customers talk to engineers they'll just get confused by the over-technical messages!

Yeah, so, good luck with that. I remember doing all that back in the '90's and it really wasn't much fun being so bloody paranoid all the time ;)

URLs:

(PS: The web2.0 companies aren't using all of the concepts of open-source, of course -- not all those web apps have their source code available for public reimplementation and cloning. I wish they were, but as I said, I can't see how that's entirely viable for every company. Not that it seems to stop the cloners, anyway. ;)

business coding community economics network-effects open-source software web2.0

links for 2006-05-26

links for 2006-05-25

links for 2006-05-23

Poll: keep 'Fixing Email Weblog' in Planet Antispam?

I added the Fixing Email weblog to Planet Antispam a while back -- however, I'm not entirely sure at this stage that its content (which is seems to be primarily news syndication) fits with the "planet" concept (which is primarily intended for first-person posts).

So -- quick poll. Let me know what you think, pro or con, Planet readers: should I remove the Fixing Email feed from that site?

Update: that was a pretty resounding 'yes'. Done!

antispam planet planet-antispam weblogs

links for 2006-05-22

Dear Recruiters

Dear Recruiters,

If you're going to (a) scrape my CV page from my website, then (b) spam me, unsolicited, offering to represent me for jobs I don't want in places I don't live, in explicit contravention of the terms of use [*] of that document -- here's a tip.

Don't compound the problem by asking me to resend the document in bloody Microsoft Word format. FFS.

([*]: Those terms were, of course, added in an attempt to stem the tide of recruiter spam. Thanks to Colm MacCarthaigh for the idea...)

clueless cv jobprofile.com jobs microsoft recruiters resume

links for 2006-05-18

Bebo's "Irish Invasion"

Reading this post at Piaras Kelly's blog, I was struck by something -- I never realised quite how bizarre the situation with Bebo is. If you check out the Google Trends 'country' tab, Ireland is the only country listed -- meaning that search volume for "bebo" is infinitesimal, by comparison, elsewhere! (Update: Ireland was the only country listed, because the URL used limited it to Ireland only. However, the point is still valid when other countries are included, too ;)

It is also destroying Myspace as a search term on the Irish internet. (Update: also fixed)

As a US-based company, they must be mystified by all this attention -- the Brazilian invasion of Orkut has nothing on this ;)

I'll recycle a comment I made on Joe Drumgoole's weblog as to why this happened:

My theory is that social networking systems, like Bebo, Myspace, linkedin, Friendster, Tribe.net, Orkut, Facebook etc. have all developed their own emergent specialisations. These are entirely driven by their users -- although the sites can attempt to push or pull in certain directions (such as Friendster banning 'non-person' accounts), fundamentally the users will drive it. All of those sites have massively different user populations; Tribe has the Burning Man crowd, Friendster the daters, Orkut the brazilians etc.

Next, I think kids of school age form a set of small set of cliques. They don't want to appear cool to friends thousands of miles away, on the internet; they want to appear cool to their peer group in their local school. So all it takes is a group of influential 'tastemakers' -- the alpha males and females in a year -- to go onto Bebo, and it becomes the site for a certain school; and given enough of that, it'll spread to other schools, and soon Bebo becomes the SNS for the irish school system. In other words, Irish kids couldn't really care less what US kids think of them; they want to be cool locally.

Also I think MySpace has a similar problem to Orkut -- it's already 'owned' by a population somewhere else, who are talking about stuff that makes little sense to Irish teenagers. As a result, it's not being used as a social system here in Ireland; instead, it's just used by musicians who want a cheap place to host a few tracks without having to set up their own website.

(Aside: part of the latter is driven by clueless local press coverage of the Arctic Monkeys -- they have latched onto their success, put the cart before the horse, and decided that they were somehow 'made' by hosting music on MySpace, rather than by the attention of their fans. duh!)

ireland irishblogs funny

links for 2006-05-17

5 Years of taint.org

Five years ago, on 15 May 2001, I started writing this weblog.

Subject matter started with a forward of something odd from the Forteana list -- 'Why Finns are sick of illnesses named after them'. In terms of subject matter, I started the weblog to reduce the amount of forwards I was passing on by email to other groups -- hence the preponderance of forteana posts early on.

Nowadays, by contrast, I try to write original ramblings^Wresearch for the main part of the site, and the occasional "fresh bits" I unearth elsewhere are kept separate, posted to the link-blog at del.icio.us/jm.

However, the real reason I started the thing was to act as an experiment in using WebMake as a blog platform -- at least, that was the excuse. It worked quite successfully, for what it's worth -- but in mid-August 2005, I eventually accepted that there weren't enough hours in the day to maintain a weblogging CMS, and its templates, as well as everything else, and that I didn't really need to test WebMake's abilities any more, and switched to WordPress. I'm glad I did; WP is a great piece of software.

So what's been the biggest hit on taint.org, by far? Here it is: http://taint.org/xfer/2004/kittens.jpg . Lots and lots of Google Image referrers, MySpace hotlinkers, etc. etc. ;) It's a top hit for a GIS search for [kittens], I think.

Random stats, based on April's logs:

  • About 81247 hits were received during April to the RSS 2.0 feed (the default), 9921 to the Atom feed, and 7795 for the RSS 1.0 rendering. That indicates that format-wars-wise, people just use the default. ;)
  • Assuming the RSS reader apps average out to 1 HTTP GET every 30 mins (as Bloglines and Apple's reader do), that means there are somewhere around (98963 / (30 * 24 * 2)) = 68 subscribers.
  • In terms of the old style browser-using readership -- there were 44926 hits on the front page using web browsers.
  • AWStats claims 2700 visits per day, from around 33000 visitors per month. I find the latter figure hard to believe.

After the front page and the feeds, the scraped RSS feeds at http://taint.org/scraped/ come second, Threadless beating out Perry Bible Fellowship by a little bit.

Top stories last month, based on hits:

  • http://taint.org/2006/04/29/230814a.html -- Single-Letter Google Hits
  • http://taint.org/2006/01/20/220239a.html -- the SweetheartsConnection.com Scam (still attracting comments from scammees!)
  • http://taint.org/2004/04/15/033025a.html -- really outdated stats on GMail's spam filtering accuracy
  • http://taint.org/2006/04/20/213624a.html -- Automatically Invoking screen(1) on Remote Logins
  • http://taint.org/2006/04/15/134751a.html -- Google Calendar
  • http://taint.org/2006/04/03/121837a.html -- A Gotcha With perl's "each()"
  • http://taint.org/2005/08/06/024026a.html -- The Life of a SpamAssassin Rule
  • http://taint.org/2006/04/21/133432a.html -- Phishing and Inept Banks
  • http://taint.org/2006/04/06/210519a.html -- RSS Feeds for Events in Dublin
  • http://taint.org/2006/04/13/140841a.html -- BT DSL's Daily Disconnects

Technorati says there are 514 links from 105 sites. I still don't know what the hell that means. ;)

Update: I've remembered that, before I started blogging at taint.org, I kept a diary at Advogato, which dates all the way back to March 2000!

Also, here are some pretty graphs from the graph-top-referers script:

The several slashdottings and a Boing Boinging are quite clear ;)

anniversary blogging blogs forteana meta taint.org webmake

links for 2006-05-12

Link-blog Networking

Cool -- del.icio.us just added a feature whereby you can now see who has you in their network, and, of course, you can further view their networks and see who's in them.

This'd be great to produce social-network graphs, although I daresay Joshua mightn't be so keen on the spidering load. ;) I've optimistically requested some form of dump, anyway.

The social networking aspect of link collection and link-blogging via del.icio.us is emerging nicely; I'm keen to see what's next in the pipeline.

A few interesting things:

  • Almost everyone who's using del.icio.us seriously for link collection -- ie. applying some quality control thresholds, and bothering to write one-line descriptions, at least -- has filled out their 'network' by now.

  • It'd be useful to have "groups", so that we can now assert things like "jm, boogah, n0wak, negatendo, tweebiscuit, leonardr, muckster and torrez form a group". I'm sure that'd provide useful info, although could probably be inferred anyway. (People are attempting to hack it by using a shared tag on all their postings, like the "irishblogs" tag, but that's an awful misuse of tagging in my opinion ;)

  • Also, it'll be interesting to see what'll happen once Google Co-op figures out a way to incorporate the del.icio.us network data. To be honest, I'm very surprised it wasn't already in there -- it seems like a no-brainer... maybe some Y!/G corporate rivalry is getting in the way.

Anyway, in the meantime it's producing lots of good fodder for my SpicyLinks feed.

SpicyLinks is an implementation of something that I mentioned in a comment on this weblog entry, regarding future methods of reading weblogs; in essence, it's an automated blog aggregation summariser. It reads other people's link-blogs, so I don't have to, and reports the stuff that proves popular in my personal collection of sources.
(Credit where due: HotLinks provided much of the inspiration, but doesn't support personalisation, hence the reimplementation.)

SpicyLinks is similar to Populicious, but that app really misses the point, in my opinion. I don't particularly want to know what everyone is pointing at; I want to know what a selected set of trusted sources (with good taste!) are pointing at.

This aggregation is pretty similar to the del.icio.us 'network' feed, but with much lower volume, and a higher signal/noise ratio, attained by dropping the 'one-off' items that only one person is pointing at. Initially, that may seem like a major failure, since you miss the 'fresh bits' -- but as long as you've got the right people in your source network, it actually works very well.

It'd be great if this was one of the features implemented in the del.icio.us 'network' system...

aggregation atom delicious feeds hotlinks link-blogs Links populicious rss social-networks spicylinks weblogs

links for 2006-05-11

links for 2006-05-10

links for 2006-05-09

Script: new-referrer-rss

new-referrer-rss.pl - generate RSS feed of new referrer URLs from access_log

SYNOPSIS

new-referrers-rss nameofsite [source ...] > new-referrers.xml

DESCRIPTION

Given the name of a web site, and a selection of Apache combined log format 'access_log' files containing referrer URL data, this will generate an RSS feed containing the latest referrers.

The script should be run periodically with 'fresh' access_log data, from cron.

access_log apache referrers scripts software web

Todd Underwood on BlueSecurity DDoS

Renesys Blog: The Bluesecurity Fiasco -- in which Todd Underwood, CSO for Renesys Corporation, applies some real-world knowledge of how the internet works to the "timeline of events" press release, issued by BlueSecurity as part of their ongoing PR about the DDoS.

Judging by the comments at Slashdot, this really needs to be more widely read.

Here's some highlights:

The timeline from BlueSecurity [...] is frustratingly vague. It uses phrases like 'tampering with the Internet backbone using a technique called "Blackhole Filtering".' As Thomas Pogge, a philosophy professor of mine, used to say: that's not even wrong yet. There is no "Internet backbone", there is no technique known as "Blackhole Filtering", and blackhole routing is not normally described as tampering. So the whole explanation is nonsense. [...] Let's clear one thing up for the press and everyone else: this event just wasn't that interesting. The attack against bluesecurity was a run-of-the-mill denial of service attack.

His conclusion:

I believe that the PR engine from BS is in overdrive spinning this event as fast as they can. But the concrete facts being put out by them simply to not add up. In the process they seem to be doing two things: 1) trying to imply or state that someone at UUnet was bribed by a spammer. This is simply ridiculous. I know many of the people who work for UUnet and they are honest, hardworking and extraordinarily clever people. They would not be crooked, or stupid, enough to do such a thing and if they were, they would have been trivially caught by change-management procedures. Moreover, such a change at UUnet (or BTN) wouldn't have caused the event BS claims to have witnessed anyway. Additionally, 2) BS is trying to deflect attention from the damage that they caused at Six Apart. It would be much better if they could just claim ignorance of the DOS, apologize and move on. I recognize that that isn't going to happen, but it sure would make this whole thing easier to handle.

Well said.

Of course, this is pretty much immaterial -- the people who are using Blue Frog, and vocally supporting Blue Security, don't really care what happened. All they care about is that someone is taking some kind of direct action against spammers, in some way or another, and if there's a little "friendly fire" and some bending of the truth, why, this is a war! What, do you support the spammers?

It's disappointing -- the amount of disinformation being successfully pumped out (and accepted!) on this story is massive.

anti-spam blue-frog bluesecurity ddos internet routing security

Outside My Window Right Now

Bubba, now safely back in Dublin after his 8000-mile flight from LAX, is getting back into exploring his old manor.

Here he is, ignoring a very brave magpie. Judging by the way the magpie was brazenly hopping around him, cawing, and the way that Bubba was ignoring him, I suspect there may be a nest nearby....

hiking home garden

links for 2006-05-04

London's Oyster RFID card to become a full cashless payment system

Apparently, Transport For London are planning 'e-money' trials based on their remotely-readable Oyster RFID cards.

Combine that with Kevin Mahaffey of Flexilis' talk at Black Hat last year, where he demonstrated apparatus to extend RFID read range from 4-6 inches to approximately 50 feet, and things could get messy. ;)

The slides for that talk are available here (PDF); slide 20 specifically mentions the Hong Kong "Octopus" cashless-payment card.

flexilis kevin-mahaffey london oyster rfid

links for 2006-05-03

Blue Frog List Leaked?

Blue Frog is a company who operates a "Do Not Email" list, on the (optimistic) basis that spammers will vet their lists against it.

Reportedly, it's been compromised. If this is true, I'm not surprised -- as Dr. Aviel Rubin's report to the FTC of May 2004 regarding a Do-Not-Email list notes:

The scrubbing approach [to running a D-N-E list] requires that a list of live email addresses exist. While the party owning that list may be well intentioned, it is unlikely that such a valuable list would not leak out. History is replete with insider attacks, as well as external break-ins to highly sensitive sites, such as the Pentagon computers. The Do Not Email Registry represents the kind of prize that attracts hackers. In this case, the prize has monetary value as well. Once the list is exposed, there is no way to undo it.

Also, it's almost inevitable:

If this service were running for some time, it is more likely than not that the plaintext addresses would leak at some point, given the history of computer security incidents.

Update: it appears, according to this white paper, that the Blue Frog "Do Not Intrude" list is hashed, rather than plain-text. Rubin's advice still applies:

Without hashing, a compromise of the registry database results in exposure of all of the registered email addresses. This is a total disaster. However, even exposure of a hashed list is a catastrophe. A spammer with a copy of a hashed list of email addresses is able to find out, for any email address, if the address is in the registry. The attacker simply hashes a candidate email address and sees if the hashed value is in the list. This is very powerful. [....]

Hashing provides absolutely no security against a marketer who obtains a scrubbed list and uses that to sell the addresses that were scrubbed by the registry. Whether or not the list is hashed has no impact on a malicious marketer in the scrubbing approach.

anti-spam blue-frog blue-security do-not-email

SpamAssassin in the Google Summer of Code 2006

Are you a student, and interested in earning $4,500 for contributing to open source, and fighting spam, over the course of the summer?

If so, get thee hence to the Google Summer of Code 2006 site, and propose a project!

Last year, we in SpamAssassin didn't get it together to mentor SoC projects. This year, however, we have a few prospective mentors (including myself), and a few sample project ideas lined up; we're all ready to go! Here's the Student FAQ. Be quick; applications end in a week and a bit.

Here's hoping we get some interesting submissions ;)

apache google gsoc2006 spamassassin summer-of-code

links for 2006-04-29

Single-Letter Google Hits

Here's what happens when you search for single letters on Google:

Interestingly I got to see the new Google search results page, with the sidebar, once. It must be in the process of rolling out...

google letters searching

links for 2006-04-27

links for 2006-04-26

Peoplefeeds and Quick Aggregation

peoplefeeds is cool.

I've been looking for something to can aggregate my Flickr, Wordpress blog, and del.icio.us feeds into one venue where I can look up items by tag, in a single page-load.

Suprglu was my leading contender, although they weren't there yet since they didn't seem to support importing my blog posts with tags preserved -- pretty much everything wound up tagged as "uncategorized". disappointing. :( so I was waiting for them to fix that.

This post by Richard MacManus pointed at another couple of options; 43Things and Peoplefeeds. I hadn't actually noticed that 43Things was doing this kind of aggregation too; unfortunately as far as I can see, they doesn't support tag preservation and browsing, so there goes my desired feature. shame.

However, Peoplefeeds was right on target, offering a 'Unified Tagspace' and a 'Search All-Personal-Content' mechanism. It works nicely, too. Here's my personal aggregator, combining my Flickr feed, my weblog feed, and my del.icio.us feed into one -- and with a unified tag-space; here's my 'hiking' tag, hitting all 3 feeds. Perfect.

One other use for this -- I've forgotten why I was looking for one of these, but I know I did want one ;) -- it can be used to make a "private planet". If you have 3 or 4 feeds that you need to combine into one, this provides a very easy way to do that; just set up a userid at Peoplefeeds for that purpose.

aggregation feeds peoplefeeds rss tags web

Phishing and Inept Banks

John-Graham Cumming asks, 'Are Citibank crazy?':

I blogged a while ago about Thunderbird's phishing filter trapping a seemingly innnocent mail. Now, a reader has forwarded to me a genuine email from Citibank that he says was trapped by Thunderbird. I'm not going to reproduce the email here because it contains private details of the user, but it is a valid Citibank message.

Thunderbird thinks it's a scam because Citibank uses one of the oldest phishing tricks in the book. The have a URL displayed in the message then when clicked goes to a totally different URL.

Sadly, this has proven to be really quite common. We've investigated using this rule as a worthwhile phish-detection rule in SpamAssassin, several times, and without much luck. In fact, we've had to create a FAQ entry for it -- since it's such a superficially-attractive but ultimately useless, idea, many people have had long discussions on our lists about it!

The companies that produce these false positives in their mails include American Express, Bed Bath & Beyond, Universal Studios, Microsoft, Hilton Hotels -- and now Citibank.

A couple of other examples from real mails:

  <a href="http://www65.americanexpress.com/clicktrk/Tracking?
    mid=MESSAGEID&msrc=ENG-ALERTS&url=
    https://www.americanexpress.com/estatement/?12345">
    https://www.americanexpress.com/estatement/?12345</a>

  <A HREF="http://echo.epsilon.com/WebServices/EchoEngine/T.aspx?l=ID">
    https://www.hilton.com/en/ww/email/tab_email_subscriptions.jhtml</A>

By the way, it really is quite impressive for a bank as heavily phished as Citibank to still be making this kind of basic mistake in their mail-outs! It reinforces a point I made in a mailing list posting recently:

As far as I can see, the approach taken by pretty much all banks to their online services is simply too bureaucratic, hide-bound, and fundamentally driven by their marketing departments, to ever cope effectively with phishing. :(

(For what it's worth, I know Citi have some smart techies working there; but the rest of the company needs to start paying attention to them.)

anti-spam banks jgc phishing rules spamassassin thunderbird

Automatically Invoking screen(1) on Remote Logins

If you routinely log into one or more remote systems using SSH, and have a flaky internet connection or an incompetent ISP, you probably already know about screen's ability to detach and reattach sessions.

However, you still have to manually type screen -r to resume a detached session, each time -- and sometimes you'll forget, start working in an SSH session, get logged out, and lose your state.

Here's the next step -- automatic screen-sessions for any remote logins: RemoteLoginAutoScreen.

howto remote-login screen scripting ssh unix

Optimo vs. Bud Rising

Optimo have a new mix up -- the First Hour Mix:

Here's the fourth in a brief series of mixes where we present something a little different. This mix isn't really a mix in the conventional sense but rather 17 tracks blended together. To us, the first hour of Optimo, or to be more accurate, the 'Espacio' part of Optimo (Espacio) is a vital part of the night. It is our chance to play absolutely what we like without thinking about the dancefloor.

It's a great mix -- certainly not dancy, but some really interesting tracks here. The Optimo guys put together some really great music.

In fact, I went to see them play last Saturday -- or, at least, myself and a couple of mates tried to. Supposedly, they were supporting The Juan Maclean at the Bud Rising festival over the weekend, but the show was such a shambles, without anyone having a clue when it started or who was on stage at any time, I'm pretty sure we missed their set entirely.

On top of that, it was EUR20 in, and to add insult to injury, the only lager on sale was Budweiser! I mean, I wouldn't mind that if the "Bud Rising Festival" deal meant free entrance, but charging 20 squids and then cutting off the supply of decent booze as well, is just a crime.

Ah well, the Filthy Dukes were pretty good at least.

bud-rising budweiser dublin festivals ireland live-music mp3 music optimo sponsorship

Google Calendar

So I've been using this for a few days now -- and I'm loving it. A calendaring system that deals coherently with the web:

I keep finding little things that make perfect sense, and just feel more logical than what I've used elsewhere. This rocks!

One thing still needs work, though: the links to Mapping fail spectacularly, for non-US addresses at least. But that's pretty minor.

By the way, I have a feeling that Mac.com had parts of this, but really, you had to drink a lot of Apple kool-aid to use that, and I just didn't go for that. Sorry Jobs fans.

Do you know what would be cool now? If Upcoming.org published venue/location-specific iCal feeds. Oh look, they do! Awesome...

calendar gcal google hcalendar http ical rss upcoming web

BT DSL's Daily Disconnects

Argh! This is what happens every day to my DSL connection, at half past 12:

13 Mon Apr 10 12:26:53 2006 PP12 -WARN  SNMP TRAP 2: link down
14 Mon Apr 10 12:26:53 2006 PP12  INFO  ppp_ready: ch:8056167c, iface:80419f14
15 Mon Apr 10 12:26:53 2006 PP12 -WARN  SNMP TRAP 3: link up
26 Tue Apr 11 12:26:46 2006 PP12 -WARN  SNMP TRAP 2: link down
28 Tue Apr 11 12:26:48 2006 PP12  INFO  ppp_ready: ch:8056167c, iface:80419f14
29 Tue Apr 11 12:26:48 2006 PP12 -WARN  SNMP TRAP 3: link up
38 Wed Apr 12 12:26:56 2006 PP12 -WARN  SNMP TRAP 2: link down
40 Wed Apr 12 12:26:58 2006 PP12  INFO  ppp_ready: ch:8056167c, iface:80419f14
41 Wed Apr 12 12:26:58 2006 PP12 -WARN  SNMP TRAP 3: link up
50 Thu Apr 13 12:27:00 2006 PP12 -WARN  SNMP TRAP 2: link down
52 Thu Apr 13 12:27:03 2006 PP12  INFO  ppp_ready: ch:8056167c, iface:80419f14
53 Thu Apr 13 12:27:03 2006 PP12 -WARN  SNMP TRAP 3: link up

Worse than that, it will generally assign a different IP address to the connection when it reconnects! This buggers up any applications that rely on long-lived TCP connections, such as SSH shell logins, tunnels, remote-desktop sessions, and instant messaging; all get disconnected and have to be manually re-set up.

Initially, I thought this may have been a flaky connection. However, it appears not -- check out those timestamps; that's a scheduled, daily event. Also, there have been no other disconnections apart from those.

A discussion on the IIU mailing list revealed the reason -- it seems BT Ireland have a policy of resetting their customers' connections daily. That could be OK, if they came right back up with the same IP -- TCP/IP is designed to cope with that, and generally does -- but it does not do that. Instead the IP address is reassigned every single time.

This is turning out to be quite a nuisance. Working over the internet requires quite a few VPN connections, tunnels, and remote logins, and having to re-set those up, daily, is turning out to be a pain in the neck.

I'm casting around for hacks to get around this. Right now, I have an assortment of jiggery-pokery involving ssh, a shell script 'while' loop, and screen(1), but it's messy and not working out too well. Ideally, I'd set up another VPN (via IPSec or CIPE), and set it up to reconnect on link failure, then route all other VPNs and remote logins out via that -- but I don't have spare routable IPs to do this with. Anyone got any good suggestions?

By the way, it's worth noting that their FAQ fails to mention this, instead giving some incorrect information about my IP being 'removed' when my web browsing session ends:

Is it a fixed IP?

No, the product is set up with dynamic IP Addressing. This means that every time you open your browser you will be allocated a different IP address for the duration of that session. When the session ends the IP Address is removed.

That is incorrect -- this has nothing to do with web browsing sessions.

To be honest, I'd prefer not to have to switch ISPs to get away from this brokenness -- the rest of the service is quite nice, good pings, good throughput, no other disconnections or outages -- but this is quite a problem for someone using BT Broadband for telecommuting purposes. :(

adsl broadband bt bt-ireland esat esatbt telecoms

Software Patenting and "Hot" Fields

Paul Graham's recent essay on his experience with software patenting has been making the rounds recently.

Now Kevin Marks has commented. Worth reading, since he demonstrates nicely the kind of crap you see in a 'hot' field, such as video (which he worked on with Apple's Quicktime):

I broadly agree with Paul Graham's essay on Software Patents, but I do think he underestimates the damage from patent trolls, and from what he calls the mafia-like behaviour of some patent holders. Paul has been lucky in the field he has worked in, but in the Audio and Video area there are many patent thickets. ... While I was at Apple on QuickTime, there was a steady stream of patent trolls claiming that Apple should pay them royalties; enough to keep several lawyers busy, and a lot of engineers spending time working on prior art evidence demonstrations. Several potential features were excluded from QuickTime due to patent thickets. The obvious one was the Unisys LZW patent that encumbered GIF, but there were other more subtle pressures that meant adopting open source codecs was discouraged. Working on the patent license agreements for MPEG meant that technology ready to ship was deferred pending legal agreement on more than one occasion.

In my experience, that's what happens -- once a field becomes "hot", patent trolls and other nuisance "inventors" start appearing en masse, and then you've got to waste a lot of time dealing with that crap.

coding patenting software swpats

RSS Feeds for Events in Dublin

So, now that I'm back in Dublin, I've taken a quick look around for ways to keep up to date on upcoming live gigs -- and found that the situation, frankly, sucks. In particular, almost none of the sites are offering RSS or Atom feeds yet.

Having said that, Waxy and Leonard's Upcoming.org is doing quite nicely for the Dublin metro area:

And lots of credit for the promoter, MCD, who seem to be just about the only Irish listings site who offer RSS:

This is fantastic, but -- naturally -- they don't cover events put on by their competitors. ;)

Apart from that, it's pretty shoddy. Lots of late-90's-looking websites out there, and no feeds in sight. Thankfully, Feed43, and some perl scripting, is on hand to allow me to take matters into my own hands.

Entertainment Ireland offer a pretty good music news section -- but sans feed. Feed43 saves the day:

And, surprisingly, Ticketmaster, of all sites, is turning out to be a great way to find out what's on in Dublin, listing pretty much all ticketed events in a nice, clean, succinct format. Unfortunately, the highest location resolution it offers for Ireland is the country as a whole. However, this can be worked around by subscribing to individual venues, such as Crawdaddy or The Village. (This has a happy side-effect of narrowing down the types of music -- I can skip finding out that The Eagles are playing, since they won't be playing at Crawdaddy ;)

For some reason, though, Ticketmaster haven't got around to offering their own RSS feeds. Not a problem -- in response I've hacked up tm2rss.cgi, a little script which scrapes the venue pages and produces RSS:

For other venues, simply take the venue URL (for example, http://www.ticketmaster.ie/venue/198641 for The Village), add the numeric venue ID in place of NNNNN in this URL: http://taint.org/scraped/tm2rss.cgi?v=NNNNN , then use that as the Feed URL in your feed reader.

atom dublin events feeds gigs ireland listings live-music rss syndication

A Gotcha With perl's "each()"

It's my bi-monthly perl blog entry, to earn my place on planet.perl.org! ;)

Here's an interesting "gotcha". Take this code:

    perl -e '%t=map{$_=>1}qw/1 2 3/;
    while(($k,$v)=each %t){print "1: $k\n"; last;}
    while(($k,$v)=each %t){print "2: $k\n";}'

In other words, iterate through all the key-value pairs in %t once, then do it again -- but exit early in the first loop.

You would expect to get something like this output:

    1: 1
    2: 1
    2: 3
    2: 2

instead, you see:

    1: 1
    2: 3
    2: 2

The "1" entry in the second loop is AWOL. Here's why -- as "perldoc -f each" notes:

There is a single iterator for each hash, shared by all "each", "keys", and "values" function calls in the program

That's all "each" calls, throughout the entire codebase, possibly in a different class entirely. Argh.

The workaround: reset the iterator using "keys" between calls to "each":

    perl -e '%t=map{$_=>1}qw/1 2 3/;
    while(($k,$v)=each %t){print "1: $k\n"; last;}
    keys %t;
    while(($k,$v)=each %t){print "2: $k\n";}'

This got us in SpamAssassin -- bug 4829.

To be honest, having to call "keys" after the loop is kludgy -- as you can see if you check the patch in bug 4829 there, we had to change from a "return inside loop" pattern to a "set variable and exit loop, reset state, then return" pattern. It'd be nice to have a scoped version of each(), instead of this global scope, so that this would work:

    perl -e '%t=map{$_=>1}qw/1 2 3/;
    { while(($k,$v)=scoped_each %t){print "1: $k\n"; last;} }
    # that each() iterator is now out of scope, so GC'd;
    # the next call uses a new iterator, starting from scratch
    { while(($k,$v)=scoped_each %t){print "2: $k\n";} }'

Scoping, of course, has the benefit of allowing "return early" patterns to work; in my opinion, those are clearer -- at the least because they require less lines of code ;)

bugs coding each perl software

Feed43 Rocks

I've just given Feed43 a go. It's very nifty.

Basically, it's a pattern-based HTML-to-RSS scraper -- similar to my own Sitescooper in that respect ;) -- but built entirely as a web app.

Until now, I've been hacking up scrapers one by one, using either Sitescooper or WWW::Mechanize, run from cron, and putting the output up on taint.org; for example, http://taint.org/scraped/ has the public ones: Threadless, Perry Bible Fellowship, and White Ninja comics.

Today, I came across a case where I wanted a new RSS feed, and since I'd been hearing of Feed43, thought I'd give it a try, to save running yet another cron on our server. It was reasonably simple, although still required a fair bit of knowledge of the concepts of scraping via pattern matching against HTML; but the UI was fantastic, with everything previewed using a clean AJAX UI, and within 3 minutes I had a new feed.

For the curious -- the feed was for TCAL's Ireland category , and the results are here: Feed43 (Feed For Free) : TCAL - Ireland. (go ahead and sign up if you like ;)

New web pattern, by the way -- there's a trend towards using "secret URLs" instead of username/password authentication for the kind of "trivial" auth task, like editing feed-scraper details. Good idea.

feed43 feeds html rss scraping syndication

Public Transit == Crime

I just received a very nice info-pack through my front door regarding the new Dublin Metro line, which is in planning at the moment; it seems they're soliciting feedback from residents near the proposed routes. Nicely done.

Right now, Dublin has an embarrassment of good public transit, at least when compared to my previous home in Orange County. There, public transit is actively campaigned against.

My favourite claim: that it 'increases crime' -- in other words that poor people from Santa Ana would come down to Irvine and steal stuff, which they couldn't do with vehicular transport, for some reason.

The OC Weekly thought it was pretty funny, too -- and an opposing group comprehensively debunked it. Still, it seemed to work; while I was living in Irvine, I got to see the Centerline proposal gradually whittled down until it was finally killed off. During that time, in contrast, Dublin built the Luas.

Unfortunately it doesn't exactly go where I want to go, but you can't always have everything. ;)

commuting dublin irvine octa ocweekly public-transit

Coffee and Trivia

Just got a new cafetiere, so I can finally switch back from instant coffee to the real deal again for my morning coffee. My productivity has doubled. Still no DSL, though -- early next week is the current estimate, and I can hardly wait.

I went to a pub quiz last night with mates Macker, Tom and Alan -- a benefit for a new Dublin theatre company, I think. The prizes were:

  • First prize: several 50 Euron vouchers for various Dublin eateries
  • Second prize: two fancy scarves, a Nivea women's cosmetics kit, and a very metrosexual Nivea bath kit for a guy
  • Third prize: 4 bottles of nice wine

We did very nicely -- "aglet" was correctly defined for instance -- but not nicely enough. Put it this way: guess who's wearing Nivea deodorant?

coffee nivea pub-quiz trivia

Buying Consumer Electronics Online, in Ireland?

Hey lazyweb, hear my plea! What are my options for buying consumer electronics online, now that I'm back in Ireland?

I like online shopping. I dislike Argos, and I really hate Dixons, Currys and all the rest of the consumer-electronics high-street operations. Get me on the net and out of the nasty little shops and I'm happy. ;)

All in all, I'm a bit of an Amazon fan. However, now that I'm back in Ireland, I've been brought back to earth with a bang on that count; the prices are OK for items at both Amazon.com and .co.uk -- but shipping is turning out to be a total disaster.

Basically, I've put in two orders, paid through the nose for basic shipping, and neither has turned up. For example -- I ordered this phone a week and a half ago, on the 9th March, ponying up UKP 27 for the item -- and a painful UKP 7 for shipping by International Mail.

Delivery estimate on ordering was for between 5 and 7 days -- 14th to the 16th March. That was long enough -- but it still hasn't turned up, and Amazon.co.uk is still claiming that that is the current estimate, despite the 16th of March being 4 days ago ;)

On top of that, it appears they don't offer any way to track the packages using that shipping method, so who knows what's happening with the damn thing right now.

If I compare that with an order I made at Amazon.com last November, in which I nabbed a handy FM transmitter for my iPod -- in that case, I got it shipped by plain old US Postal Service for $4.51, which was handily discounted as Super Saver Shipping. That -- as with pretty much all my Amazon.com orders -- arrived in 3-4 days, and for a hell of a lot cheaper too. If I'd had to pay for shipping (which I didn't anyway), $4.51 vs UKP 7 works out as a third of the price, no less.

I'm guessing this is mainly down to Amazon.co.uk being shoddy in terms of how it deals with shipping to Ireland, and there are probably sites that use better-quality shipping partners.

Surely there must be better deals with vendors in Ireland, or even elsewhere in the Eurozone? Anyone know? Please drop us a line in the comments!

Update: the items arrived -- 14 days after ordering. This is a moot point now, though, since Amazon.co.uk are no longer selling 'PC & Video Games, Toys & Games, Gift items, Electronics & Photo and Home & Garden items' to Ireland; I guess it was easier to give up on the Irish market for now. Very disappointing -- but I'm waiting to see what happens next.

amazon e-commerce ireland retail shipping shopping

Greetings from 1996!

    --> Sending: ATZ
    ATZ
    OK
    --> Sending: ATQ0 V1 E1 S0=0 &C1 &D2
    ATQ0 V1 E1 S0=0 &C1 &D2
    OK
    --> Sending: ATH1
    ATH1
    OK
    --> Modem initialized.
    --> Sending: ATDT1892150150
    --> Waiting for carrier.
    ATDT1892150150
    CONNECT 45333

45 measly kilobits per second! This is incredibly painful -- and expensive at 5 cents a minute! I briefly considered getting around it by hiring a 3G data-card for the couple of weeks before my DSL is activated -- but that too is insanely overpriced.

Hurry up, DSL...

1996 45kbps ath0 dialup eircon internet ireland modems retro

Disclosure

As of yesterday, I have a new day-job.

I won't be working on email spam as part of the job, which is an interesting turn of events. However, I'll be sticking with the open-source Apache SpamAssassin project, and keeping up the rate of work on that [*].

I'm not sure how much I can blog about the new place just yet, but I will say it's certainly looking like it'll be very interesting work ;)

[*: modulo the next couple of weeks while I'm waiting for my bloody DSL to be installed. argh!]

jobs life spamassassin work

Apple Attempting to Patent RSS Aggregation

Miguel de Icaza quotes Dave Winer, pointing out two patent applications from Apple which seem intended to grab major chunks of the feed syndication space as Apple "IP".

The first application is news feed viewer, 20050289147, filed April 13 2005:

A computer-implemented method for displaying a plurality of articles, the method comprising: storing a first feed bookmark in a folder, the first feed bookmark indicating a first feed, the first feed comprising a first plurality of articles; storing a second feed bookmark in the folder, the second feed bookmark indicating a second feed, the second feed comprising a second plurality of articles; aggregating the first feed and the second feed to form a third feed; and displaying the third feed.

I think there were many RSS readers that implemented this, and others from the patent application, before April 2005. I know Liferea, the one I use, has had UI-level aggregation since September 2004, with its VFolders.

Next, news feed browser, 20050289468, filed April 13 2005. This one contains a wide range of claims, but here's one that stands out as particularly trivial:

A computer-implemented method for discovering a feed, the method comprising: receiving a request to display a file; determining that the file includes relationship XML; determining that a Uniform Resource Locator (URL) within the relationship XML indicates a file that comprises the feed; and displaying one of a group containing the feed and a link to the feed.

That's pretty much RSS autodiscovery, as described in 2002.

The listed inventors in both patents are: Kahn, Jessica; (San Francisco, CA) ; Alfke, Jens; (San Jose, CA) ; Wilkin, Sarah Anne; (Menlo Park, CA) ; Howard, Albert Riley JR.; (Sunnyvale, CA) ; Forstall, Scott James; (Mountain View, CA) ; Lemay, Stephen O.; (San Francisco, CA) ; Melton, Donald Dale; (San Carlos, CA) ; Loofbourrow, Wayne Russell; (San Jose, CA).

Thanks, Apple! and thanks, "inventors"!

It's important to note that this is still in the application stage, and as such can be invalidated, or narrowed down to a saner level, by using the techniques described here. I strongly recommend that people working in the syndication field with sufficient knowledge and expertise who feel strongly enough about this should spend a little time doing so, before the patent is issued and it becomes a multi-million-dollar task to invalidate it. (however, IANApatentL of course ;)

apple feeds patent-applications patents rss uspto

We Win

ongoing: The ASF Server:

Tim Bray: Which Apache project burns the most resources?

Mads: Spamassassin by a wide margin. [...]

Heh, we win ;)

Helios, the Zones server, has been an incredible resource for us. SpamAssassin isn't a traditional open-source software project in one respect: we use a lot of centralized "phone home" infrastructure to support rule and score generation. Having a virtualized server of this quality and horsepower to use for this has been fantastic.

(thanks to John O'Shea for the pointer!)

apache asf funny heh solaris solaris-zones spamassassin virtualization

IBM Patents Closed-Loop Confirmation

Another day, another absurd IBM software patent. Via the IP list, here's United States Patent 7,003,497:

  1. A method for confirming an electronic transaction, comprising the steps of: performing an electronic transaction between a first party and a second party; providing, by the first party to the second party, contact information of a third party service provider associated with the first party; contacting, by the second party, the third party service provider to obtain a location of a predetermined, private mailbox associated with the first party; sending, by the second party, a request for confirmation of the electronic transaction to the predetermined, private mailbox associated with the first party; accessing the private mailbox by the first party; and sending, by the first party, a reply message to the request for confirmation to thereby confirm authorization of the electronic transaction, wherein information regarding the private mailbox is not communicated to the second party during the electronic transaction.

There's lots of waffle in the background section about this being for electronic e-commerce transactions, but that claim, and claims 2 and 3 at least, are easily sufficiently broad to cover simple "confirmed opt-in" email subscription systems -- in other words, the system whereby a potential newsletter subscriber clicks on a link in order to "confirm" that they want to subscribe to a newsletter. That's the current best practice email subscription method used by pretty much everyone.

Filed December 31, 2001. There was plenty of prior art before this date, but who would want to go up against IBM, no less, to attempt to get this invalidated, especially now that it's been issued?

Thanks USPTO, you're doing a heck of a job!

email ibm mailing-lists patents subscription uspto

US Things I Miss

So, I've been back in Ireland for several weeks now. How goes the culture shock? Well, let's make a list of the stuff I'm missing from California:

  • C, who's still back there finishing up her contract. Hurry up, C!

  • All my friends I left behind in the US :( Come visit!

  • The weather (well duh)

  • Trader Joes: low-cost, high-quality organic and near-organic food

  • The excellent Mexican and Southern food. Mmm, Taco Mesa

  • Super-cheap cocktails -- although having good Guinness makes up for a lot of this

  • The back country -- desert, mountains, snow, national parks. Ireland may have more surviving history dotted about, but it's just flat. I miss the mountains

  • Netflix -- haven't spotted a replacement for this yet. There are companies in Ireland that use a similar idea, but it appears every one just about manages to screw it up and render it useless, generally by introducing throttling, late fees, or slow turnaround. meh

  • The way my Irish accent meant I could get away with pretty much anything. That trick doesn't work in Ireland ;)

In other news: the broadband choices situation has pretty much gone to shit.

It turns out that all the good options are quite dependent on local-loop unbundling, which -- somehow -- still hasn't gotten around to my local exchange. As a result, guess who's going to be stuck on the wrong end of dialup, no less, for "2 to 3 weeks" until Eircom deign to switch on the bitstream access for my new BT-resold ADSL connection? Here's hoping there's a neighbour with broadband and wifi when I move back in. Joy.

broadband california food ireland life lists llu netflix travel us

DearAOL and GoodMail

Things have really been heating up recently around the AOL/Goodmail "pay to send" CertifiedMail scheme -- the EFF and a host of other groups have launched dearaol.com, stating:

This system would create a two-tiered Internet in which affluent mass emailers could pay AOL a fee that amounts to an "email tax" for every email sent, in return for a guarantee that such messages would bypass spam filters and go directly to AOL members' inboxes. Those who did not pay the "email tax" would increasingly be left behind with unreliable service. Your customers expect that your first obligation is to deliver all of their wanted mail, and this plan is a step away from that obligation.

While I dislike this proposal, too, as far as I can tell, AOL actually have pretty reasonable intentions with this program -- nowhere near as bad as the DearAOL.com site makes out.

However, they're doing a really really crappy job of getting this information out there, or committing to reasonable limits on the program, such as announcing that they will use it only for transactional emails, as Yahoo! have done.

I'd strongly recommend reading Carl Hutzler's posting on the subject. Carl was AOL's head of anti-spam operations until last year, so he really knows what he's talking about, and he lays it out clearly -- a lot more clearly than any corporate statements from AOL do. His blog contains a fair bit more on the subject, too.

But seriously -- why isn't there a press release on the AOL site about this scheme? Some front-channel communication about now might be useful, I'd suggest, before things really get hairy -- this crapstorm is coming about partly because AOL's comments are all filtering out in drips and drabs via third parties, and (AOLers say) are being misconstrued and misrepresented in the process. It's a classic case of missing the cluetrain.

I'd also really encourage the EFF people to tone done the rhetoric; statements like "senders will have no guarantee that their emails will be delivered" is scare-mongering, given that SMTP email already provides no such guarantee.

Update: wow, MoveOn went really overboard -- "threatening the Internet as we know it ... The very existence of online civic participation and the free Internet as we know it are under attack." OMG the sky is falling!

Side Issue: The Spam Definition

Also, another note to EFF: defining spam as "whatever you don't want to read" is a terrible mistake to make. That confuses a good, clear, enforceable and automatable definition of spam -- unsolicited bulk email -- and makes it effectively unenforceable by law, unpoliceable by ISPs, impossible to detect automatically, and incompatible with existing, effective EU and Australian legislation.

Listen to your own Chairman of the Board; he's right on this count.

PS: any luck fixing up the non-confirmed signups issue? Last time I checked I could still subscribe any address to the EFF Action Alerts without a cross-check, which is not a good thing.

anti-spam aol defining-spam eff goodmail pay-to-send spam ube

Another script: goog-love.pl

A quick hack --

goog-love.pl - find out where your site's google juice comes from

This script will grind through your web site's "access.log" file (which must be in the "combined" log format). It'll pick out the top 100 Google searches found in the referer field, re-run those searches, and determine which ones are giving your website all the linky Google love -- in other words, the searches that your site 'wins' on.

The output is in plain text and a chunk of HTML.

usage:

goog-love.pl sitehost google-api-key < access.log > out.html

e.g.

cat /var/www/logs/taint.org.* | goog-love.pl \
  taint.org 0xb0bd0bb5yourgoogleapikeyhere0xdeadbeef | tee out.html

NOTE: this script requires the SOAP::Lite module be installed. Install it using apt-get install libsoap-lite-perl or cpan SOAP::Lite. It also requires a Google API key.

For example, here are the current results for this site. You can immediately see some interesting stuff that's not immediately obvious otherwise, such as my site being the top hit for [beardy justin] ;)

Download here (5 KiB perl script).

Notes:

  • if you see a lot of "502 Bad Gateway" errors, it's probably over-zealous anti-bot ACLs on Google's side. Try from another host.

  • Read the comments for notes on a bug in recent releases of SOAP::Lite; please let me know if you hear of them getting fixed ;)

goog-love.pl google hacks perl scripts searching software

Dublin Riots

While driving around Ireland on a wedding-location-scouting trip, we started receiving texts talking about riots in Dublin; I texted a friend, and got a reply along these lines: "Celtic-topped scobes run riot through O'Connell St, torching cars in Nassau street, hospitalising cops and Charlie Bird. madness!"

I thought he was joking, but nope. A load of IRA-slogan-shouting scumbags really had been allowed to run riot -- with paving stones of all things left unsecured in their midst! -- and it quickly got way, way out of hand.

The blog coverage is excellent, with lots of photos. I suggest starting with Indymedia Ireland, these Flickr photos and the links on this weblog. It appears the gardai really fell down on this one.

For what it's worth, I was in town a few hours later, and the rest of Dublin was trouble-free -- just the usual Saturday night goings-on. O'Connell St. was still a rubble-strewn mess when I passed through on Sunday, though.

dublin ireland policing politics riots

SourceForge.net now offering public Subversion

Good news. It appears that SourceForge are now offering full, public use of Subversion for all projects on sf.net!

The SourceForge.net: Subversion (Version Control for Source Code) document contains full details on their setup. Notable key points:

  1. It's using authenticated HTTPS -- which is great, going by my experiences with the ASF's setup
  2. Imports are done from either an existing SF.net CVS repository using cvs2svn, from a Subversion 'svnadmin dump' file, or from a CVS repository tarball
  3. CIAbot support is offered as standard ;)

Awesome. I'll be trying this out with Uffizi, which I registered as a Sourceforge project a few weeks ago just to try this out. ;)

subversion_svn_sourceforge_open-source_projects_softwar

TREC Spam Corpus

Some news from TREC's Gordon Cormack:

The TREC 2005 Corpus (92,000 messages - 42,000 ham; 50,000 spam) is now available for self-serve download.

TREC Spam Evaluation is a NIST program to develop methods to measure spam filter accuracy and performance. More details here.

The corpus can be picked up at Gordon's site. As far as I can tell, this should be a pretty solid corpus for spam researchers and developers.

corpus download evaluation filter ham news nist program spam trec

Four Things

I don't do silly blog antics much, but I got tagged by Mat for the Four Things meme. Looking around, it is indeed a bit more interesting than things like the usual LJ quiz, so why not!

I wrote this on the plane from LA to Dublin, which may have affected some of the selections in 4 places I would rather be right now at least ;)

4 jobs I've had:

  • I was Iona Technologies' first employee, and stayed there for no less than 7 years. I got to see the company grow from a handful of people, most of whom weren't getting paid (hence how I wound up as the first employee ;), all the way up to a 300-strong multinational, while the company itself formed a core of Ireland's mini dot-com boom. That was fantastic fun, and educational to boot.

  • my Dad's gun/fishing/sporting-goods shop. Was it really a good idea to have a teenager working near firearms? At least I wasn't the one who unplugged the fridge where the maggots were kept, so that they all hatched over the course of one weekend...

  • A horrible teenage job -- picking tomatoes. I can still feel the orange dust under my fingernails every time I smell fresh tomatoes :( I didn't last very long at that at all.

  • writing an Amiga-based kiosk system for virtually no pay whatsoever, at the age of 18 or 19. Ah, exploitation.

4 movies I can watch over and over:

  • Koyaanisqatsi -- it's dating a little now, since every ad agency through the 90s ripped it off. But still, the invention of a new format. I remember looking at the 405 freeway in LA, and thinking "looks like something out of Koyaanisqatsi" -- of course, it was.

  • Princess Mononoke -- either that, or Nausicaa. I just love the way the characters are coloured in shades of grey, rather than black and white.

  • the Lord of the Rings trilogy -- oh dear I'm a hopeless Tolkien fanboy.

  • Spinal Tap -- pure genius.

4 places I've lived:

  • Melbourne, Australia; around the time of the annoying TV drama, The Secret Lives Of Us;

  • Newport Beach, CA; around the time of the annoying TV drama, The O.C.;

  • Dublin, Ireland; no annoying TV drama -- so far

  • University of California Irvine, CA; while Irvine itself is the most soulless suburban hellhole I've ever visited, living on the UCI campus is quite fun by comparison. Take about 1000 grad students, post-docs and lecturers from around the world; put them all in the same square mile or so; remove all fun (and bars!) from the surrounding areas; watch them make their own entertainment, or go mad.

4 tv shows I love:

4 places I've vacationed:

  • Annapurna Base Camp, Nepal; we trekked our way up to there, then trekked back down again. Unforgettable. I really want to do another Nepal trek as a result

  • car-camping around the Australian state of Victoria; they have some fantastic national park campsites, which most tourists overlook

  • learning how to dive in Ko Tao, Thailand; great setting, great dive sites, pretty cheap too!

  • Yosemite; amazing, world-class natural beauty. Californians don't realise just how lucky they've got it ;)

4 of my favourite dishes:

  • A good Thai green curry

  • Laos-style green papaya salad with sticky rice

  • a good meaty cassoulet, from Fandango in San Luis Obispo. At least, that was the tastiest meal I've had in recent months ;)

  • Mangosteen -- the queen of fruit, according to the Thais. I could, and probably have, eaten hundreds of these

4 places I would rather be right now:

  • spending New Year's Day with a bunch of friends in rural West Cork or County Galway; until I moved to the US, this was one of my favourite annual traditions.

  • the Stag's Head Bar, Dublin, in the snug, again with a bunch of friends

  • sitting on the grass outside the Pavilion bar in TCD, on a sunny summer's day (hmm, that's a lot of bars!)

  • Chiang Mai, Thailand

4 sites I visit daily:

4 people I'm tagging:

four-things fun history life memes weblog

The Return of Sneakernet

Keith Dawson sent this on -- an interview with Jim Gray, head of Microsoft's Bay Area Research Center and winner of the ACM Turing Award, talking about new transmission systems for truly massive data collections. Very interesting:

[One] option is to send whole computers. .... We're now into the 2-terabyte realm, so we can't actually send a single disk; we need to send a bunch of disks. It's convenient to send them packaged inside a metal box that just happens to have a processor in it. I know this sounds crazy -- but you get an NFS or CIFS server and most people can just plug the thing into the wall and into the network and then copy the data.

Dave Patterson, interviewer: What's the difference in cost between sending a disk and sending a computer?

JG: If I were to send you only one disk, the cost would be double -- something like $400 to send you a computer versus $200 to send you a disk. But I am sending bricks holding more than a terabyte of data -- and the disks are more than 50 percent of the system cost. Presumably, these bricks circulate and don't get consumed by one use.

DP: Are you sending them a whole PC?

JG: Yes, an Athlon with a Gigabit Ethernet interface, a gigabyte of RAM, and seven 300-GB disks -- all for about $3,000.

DP: It's your capital cost to implement the Jim Gray version of "Netflicks." (jm: sic)

JG: Right. We built more than 20 of these boxes we call TeraScale SneakerNet boxes. Three of them are in circulation. We have a dozen doing TeraServer work; we have about eight in our lab for video archives, backups, and so on. It's real convenient to have 40 TB of storage to work with if you are a database guy. Remember the old days and the original eight-inch floppy disks? These are just much bigger.

DP: "Sneaker net" was when you used your sneakers to transport data?

JG: In the old days, sneaker net was the notion that you would pull out floppy disks, run across the room in your sneakers, and plug the floppy into another machine. This is just TeraScale SneakerNet. You write your terabytes onto this thing and ship it out to your pals. Some of our pals are extremely well connected -- they are part of Internet 2, Virtual Business Networks (VBNs), and the Next Generation Internet (NGI). Even so, it takes them a long time to copy a gigabyte. Copy a terabyte? It takes them a very, very long time across the networks they have.

bandwidth disks fedex jim-gray ms-research shipping sneakernet storage terabytes ups

E-Pending

Boing Boing has an interesting case today:

"I filled out a web form for a contest from Miller using a throwaway junk email address and then, months after I dumped the throwaway account, I got this to my main account! Not sure I like the idea of companies tracking me down like this."

I sent a mail to follow up on this, but it's worth blogging here too.

This is, unfortunately, common practice among the "legitimate" bulk mailer companies; it's called "e-pending" (short for "email address appending"). Basically, the advertiser contacts one of the big data-mining companies, provides them with the data they have about the customer -- name, postal address, etc., and gets them to match that against their database; the data-miner then provides any other email addresses they may have on file for that user, even if those email addrs were provided for bills, promotional use for other companies, etc.

The advertisers contend that permission was given by the person who's being mailed; the recipients contend that permission was given to send to a specific address, not all of that person's addresses in perpetuity.

Here's a few more examples of e-pending gone bad: two Jennifer Millers, Sony scraping ancient Internic contact addresses, Spamvertized.org comment on the practice, Joe St. Sauver comments.

It's exclusively a US phenomenon, as far as I know; I think most cases of e-pending are rendered illegal under EU data protection law. Handy. ;)

Update: Brian at the Spam Kings weblog notes that 'this spooky little spam was the work of Equifax, the big credit reporting agency that shut down its Boca Raton-based spam operation, Naviant, in 2003, due to the impending passage of CAN-SPAM.'

bulk-mail data-mining data-protection email epending privacy spam

RFID in the Grauniad, and back in Dublin

Greetings from sunny Dublin, Ireland! (really!)

I'm now back in taint.org's native timezone, although precariously set up and experiencing occasional interruptions. If you're waiting for a mail from me, it may take a little more time.

I did have time to be interviewed last week by Karlin Lillington for this Guardian story:

To make sure customs agents could read his cat's chip to match him to his Pet Passport on return to Europe, Mason bought his own scanner at a cost of some £200. "I didn't want to risk the cat being impounded for six months' quarantine at Heathrow," he sighs.

It's true.

Happy to be back -- I think. Looking forward to my first pints, in over a year, of creamy Guinness in its native habitat. I also have a couple of half-written weblog entries I wrote on the plane, too...

bubba cat dublin guardian guinness home meta rfid travel

Yahoo! delete b3ta newsletter mailing list?

Today's top item on the b3ta front page, under Site News:

Yahoo please talk to us! Help! - our yahoogroups list (with over 100,000 subscribers) has been deleted. We don't know why. If you work at Yahoo and can help us sort this out please contact me at robmanuel AT gmail dot com.

posted by rob on 10th Feb at 2pm

B3ta is a long-established UK humour site who send out a weekly newsletter, every Friday afternoon, using Yahoo! Groups as their mailing list service. They've been doing this for years. Yep, that's 100,000 subscribers.

Anyway, if anyone from Y!Groups, or anyone who knows someone there, is reading, please do get in touch with the b3ta guys -- this is a very serious catastrophe for them. I'd be curious to hear how/why this happened.

To tie this into spam-filtering and email operational topics, it brought this posting from Jeremy Zawodny to mind:

This all makes me wonder if it's worth it for smaller organizations to bother running their own mail servers anymore. If Google offered small business mail the way Yahoo does, there'd be some serious competition in the market and it'd make a lot of people's lives much easier.

While Jeremy was talking about a different service from list hosting, I think we're seeing the other side of the email-outsourcing coin, here.

Update: fwiw, it's back:

Yahoo update - on Friday Yahoo deleted our list of 100,000 newsletter readers email addresses, hence we didn't send a newsletter. Today they've been in touch and have promised a response by Tuesday. Fingers crossed. UPDATE: It looks like it's back! Hooray for Yahoo!

b3ta email mailing-lists newsletters outsourcing yahoo

Broadband choices in Ireland

Perfect timing! Just 5 days before I return to Ireland, Damien Mulley posts 'Broadband choices in Ireland', a good overview of the options available for consumer broadband internet connection.

I've been out of the loop for quite a while, and spoilt by the options available in suburban Southern California (which are, of course, pretty good). But this is a lot better than what was on the table when I left, 3 years ago.

What strikes me is that the upload/download speeds are quite reasonable and pretty close to what you'd see in the US. Similarly, the prices are finally near to the going rate in the US, once the various limitations and add-ons (required 'bundles', state taxes etc.) are taken into consideration.

However, virtually all of these deals use the horrendous concept of download capping! Given that I use this stuff for work, and routinely rsync around 30GB chunks of email corpora between central offices, colo servers, and my desktop, this just won't fly. It could be argued that I'm therefore not a typical broadband consumer, who these deals have been carefully designed to cater for. But seriously -- if a telecommuting software developer isn't a typical broadband consumer, who the hell is? Hey telcos: a little flexibility goes a long way -- don't fence me in. ;)

All in all, it looks like Smart Telecom are the winners; 3Mb/s download, 512Kb upload -- and most importantly, no cap -- for EUR 35 per month. (And check out that XHTML/WAI-compliant website!)

I probably would have gone with Irish Broadband, but for the past 6 months the only thing I've been hearing about them via word-of-mouth has been bad news, detailing customer service meltdown after meltdown. Even the legendarily incompetent 'biddies' of Eircom seem to be getting better reviews nowadays.

Talking of Eircon, our dear old dirty-tricks-wielding celtic-tiger-throttling incumbent telco: the top Sponsored Link on a Google search for irish broadband is:

Irish Broadband

www.eircom.ie -- More speed, prices reduced by 25%, free modem & a free connection!

Scum.

adsl broadband damien-mulley eircon ireland irelandoffline irishblogs smart-telecom

Spamhaus comment on the AOL/Goodmail deal

AOL and Yahoo! have been making a lot of headlines with their plans to reduce their whitelist-management workload -- and make a little pay-to-send money on the side -- with a deal with Goodmail.

Now Spamhaus have gone on the record against the plan:

On Monday, Richard Cox, chief information officer at antispam organization Spamhaus, said that "an e-mail charge will destroy the spirit of the Internet."

"The Internet has become what it is because of freedom of communication. Open discussion is what gives it value. There should be no cost for particular services, and e-mail should be free and accessible to all. This will disenfranchise people."

anti-spam aol goodmail pay-to-send spam spamhaus whitelisting

RFID "e-Passports"

This is what passports containing RFID chips will look like:

Note the little rectangular logo at the bottom. According to Ed Hasbrouck, that's the ICAO standard logo indicating that this is an RFID passport, and therefore:

identity thieves, terrorists, direct marketers, data aggregators, malicious governments, or anyone else with a radio receiver within 10 meters (30+ feet) or more whenever your passport is read at a border crossing, airport, etc. can secretly and remotely track you, log your movements through the unique "collision avoidance" ID number sent by the chip, and intercept and decrypt all the data (including your digital photo and, in some countries, your digitized fingerprints) needed to "clone" a perfect copy of your passport, forge other identity credentials, or impersonate you.

Of relevance are the comments over at Bruce Schneier's weblog entry regarding the Riscure research into the Dutch Biometric Passport's lousy security.

Interestingly, as one commenter there notes, breaking the crypto may be overkill; the knowledge that a person is carrying a passport from a certain country, or set of countries, may be enough for certain attackers.

I asked the Irish Passport Office about their RFID plans last April:

I'm an Irish citizen and passport-holder. I have been following recent discussions in the US regarding the addition of RFID computer chips to US passports, and I note that the US Department of State is now indicating that this measure was made necessary due to recent International Civil Aviation Organization (ICAO) standards -- namely ICAO Doc 9303.

As a result, since Ireland is a signatory to ICAO regulations, this raises the question as to whether Irish passports shall shortly include similar RFID or "contactless chip" technology.

Can you tell me:

  • if this is planned?

  • is there a mechanism for public comment on this process?

  • who could I further email to ask about this, if you do not know?

Disappointingly, I never received a reply. :( Someday I should really chase this up.

Update, Oct 17 2006: Well, they never bothered replying. They did, however, introduce RFID chips to Irish passports:

The chip technology allows the information stored in an Electronic Passport to be read by special chip readers at a close distance. The chip incorporates digital signature technology to verify the authenticity of the data stored on the chip.

eu icao ireland passports rfid riscure security

OpenWRT Wifi Repeater Recipe

Seeing as I've moved house, and am staying at a friend's temporarily until I head back to .ie, internet access has become a bit of a problem. Hence, I'm posting this via some neighbour's leeched wifi ;)

To do this, I came up with some seriously hacky IP infrastructure, to wit a repeater setup composed of two off-the-shelf router/NAT/AP boxes, since the signal is pretty weak and needed a boost to cover the useful parts of the house. If you're curious. the details can be read over here.

wifi_openwrt_wrt_networking_routers

Weblog Spam and Adversarial Classification

Dr. Dave, author of the Spam Karma WordPress antispam plugin, has posted an interesting article about new weblog-spammer tactics:

These spams do not present most of the idiotic traits of their lower colleagues: they do not try cramming hundreds of URLs or inserting hundreds of easily spotted junk keywords in the comment content. Instead, they use only the dedicated name and homepage fields to sneak in spam URL and keywords. The comment content is often perfectly innocuous, sometimes even topical (by copying parts of another comment or a trackbacking post). All in all, these spams could easily be missed by a human moderator who wouldn't look carefully at the contact name and URL.

(Thanks to Kelson Vibber for the pointer to this.)

In other words, he is noting what we noticed in email anti-spam; that what works well one year, is likely to degrade over time as the spammers attempt to evade it, and one has to keep working to keep up.

The best term for this appears to be adversarial classification. Anti-spam activities fall into this category, and it often means that classic text classification algorithms aren't suitable -- after all, the Reuters-21578 dataset never tried to evade your classifier ;)

In a similar vein, this MS research paper is interesting:

Previous work on adversarial classification has made the unrealistic assumption that the attacker has perfect knowledge of the classifier. .... We present efficient algorithms for reverse engineering linear classifiers with either continuous or Boolean features and demonstrate their effectiveness using real data from the domain of spam filtering.

It's akin to John Graham-Cumming's work looking into how a spammer could get past a bayesian filter "from the outside", but with more techniques, and examining MS' MaxEnt algorithm, too. PDF here, well worth a read.

(By the way, I'm in the process of moving house, so if you send me an email, it may take a while for me to reply. This situation is likely to prevail for the next few weeks, for what it's worth -- fun.)

adversarial-classification anti-spam maxent papers spam-karma weblogs wordpress

Raw Food Crackpottery

Via RobotWisdom, a review of a new Primrose Hill cafe:

No wheat. No gluten. No sugar. No GMO. No dairy. No yeast. No shoes.

Yep, no shoes. If you want to enjoy the detoxifying glories of London's first raw-food cafe, then please leave your clod-hoppers at the door, along with your high stress levels and your smart-arse scepticism.

I know of another cafe elsewhere which also offered a largely-raw menu. This one, however, shared a back alleyway with a shop where a friend of mine worked.

He noted that on several occasions, he'd seen rats near, or on, the pallets of plastic-wrapped fruit and vegetables. You see, the raw food was delivered to the kitchen door, where it laid outside for a short while -- in the rat-infested alleyway. Rats crawling over your food, naturally, is not a good thing.

There's a very good reason why some smart stone-age ancestor invented cooking our food -- because it kills the germs that'll make us sick!

Devotees claim that because the enzymes are destroyed when food is heated above 48C, our bodies have to utilise our own enzymes to break down the food, which can result in us feeling tired and run-down.

Yeah, devotees are pretty much talking crap there. ;) If anything, cooked food is easier to digest than raw. And good luck with the whole 'getting by without using enzymes' thing!

What a load of quackery.

alleyway cafe door food gluten review robotwisdom thing via wheat

Happy Spam-Solved Day!

Happy BillG-Scheduled Spam Solved Day!

"Two years from now, spam will be solved," Microsoft's Bill Gates said [at the 2004 World Economic Forum in Switzerland].

So is it? Weeeeell.....

To "solve" the problem for consumers in the short run doesn't require eliminating spam entirely, said Ryan Hamlin, the general manager who oversees [Microsoft]'s anti-spam programs. Rather, he said, the idea is to contain it to the point that its impact on in-boxes is minor.

In that way, Hamlin said, Gates' prediction has come true for people using the right tactics and advanced filtering technology.

Ha. I am reminded of 'weapons of mass destruction-related program activities'.

As one slashdotter says, 'when you fail, try try again; or conversely, change the requirements and make it look like a success, which is exactly what BG has done.'

It's not washing, though, unsurprisingly. The poll on the same page, asks 'do you agree with Microsoft's contention that the spam problem has been "solved"?' Right now, with 1169 votes, it has 7.2% (in other words, the MS employees) agreeing, and a whopping 92.8% not going for it.

anti-spam billg dark-is-the-new-standard end-of-spam-day funny microsoft spam

SweetheartsConnection.com - Interesting Dating Scam

Here's an interesting online scam. An anonymous friend, working in anti-spam, writes:

'I've been covertly looking into rumours of a myspace scam and thought you might like to blog it - I don't want to be attached to this in any way otherwise I'd write about it myself (I have a profile on there that I want to keep around in case other scams show up, but I don't really want to advertise the profile).

It works like this:

You sign up for a myspace account and fill in your profile details. Then in a couple of days someone contacts you pretending they're using their friend's account because they haven't signed up yet. They say something along the lines of "I saw your profile and thought you were cute, if you're interested email me at (random)@yahoo". If you email them, you get a reply back being all bubbly and cute, and a link to a web page that sort of looks like a "My First Homepage" - it even says "I'm taking a course at the community college in HTML". There are pics on the page of a very cute girl, but at the bottom a teaser saucy picture in lingerie, and an Adult Pass signup to get more pics. Of course the signup is $40.

It's a subtle scam, but definitely a scam. Here's an example of the type of site you get sent to:

http://www.honesthost5mb.com/kristenssite/

Note the hosting service. Now delete the /kristenssite/ part and it looks legit, right? Until you click on a few links and realise they have nothing to sell.

Google has no knowledge of honesthost5mb - nobody links to them, so how did Kristen find them?

It's indeed quite funny that there's a terribly similar hosting service out there: http://www.jagflyhosting.com/ - yet for some reason all their links seem to work, and they have an accessible phone number. Shock. Horror!

I'm pretty sure the account being (ab)used on myspace is a stolen one - it looks pretty legit, including linked in friends and comments, so I'm suspecting a cracked password.

Anyway, thought you could blog this to warn others about it (feel free to advertise the above link - though I guess that'll ruin the whole "google doesn't know" thing ;-) I wish I had the guts to sign up for the extra pics to see what you end up with!'

They also passed on the email content, noting 'here's the email sent from yahoo webmail from an AOL account (sadly AOL proxies all web content so I can't track it any further than New York proxies)':

Hi [redacted] ! Hey you found me! I was a little worried you wouldn't be able to :P so, how are you? I'm ok.. I'm sneaking a email in at work before my boss comes back in, so sorry if it's a little short! I promise to write more later :)

So I promised you some pics:P well I will have to send you some of me when I get home (don't have the pics here at work). In the meantime you can check out my personal homepage. It's kind of playground while I'm taking this intro to HTML class, kind of like my blog page. Here is the link: http://www.honesthost5mb.com/kristenssite It's not much yet but it's getting there. hehe

So tell me more about yourself, are you a work to live or live to work kinda person? What are you looking for in a girl? Do you like myspace? I think I'll make a profile soon, it's free right? and you can add your own HTML? That would be cool.. So how is your 2006 going? Mine is ok, one thing I'm excited about though is that today is exactly 1 week before my birthday. Hey, maybe if we hit it off, we can go on a first date on my birthday, that would be really cool. :)

Anyways, enough with the 20 questions right? oh, I prefer to chat on IM, its more personal you know? Do you have AIM? im kriskat224 on there, msg me sometime ok?

Well I should log off and get some work done.. Write back soon! and take care!

xoxo ~ Kristen

Sure enough, a little further research on Google yields the following examples...

The earliest is this story at Jiveworld.net, of 2004-05-24, noting:

Aaron recently received an e-mail from someone he supposedly chatted with on Match.com:

Aaron: I had actually been chatting with someone I might have met there a LONG time ago. I couldn't remember, so I gave her the benefit of the doubt. I thought it was SPAM, but hey, even my own e-mails sounds like SPAM sometimes. She sent me a picture in her e-mail, but the mail service she was using didn't like it. So she sent me the link to her "website." It initially seemed like a real personal web space until the big ADULT BUREAU logo appeared. Oh yes, very legitimate.

This was a unique experience for me since someone actually wrote a tailored response to my e-mail, responding to specific things I had mentioned. Even though the bulk of the e-mail seemed form generated, this had to have been a time intensive process for damn near no return. Well, after the ADULT thing, I thought my response to her e-mail was inventive. Since I haven't received another response, it's obvious she (Or he) took the hint.

Another: a thread at FordPower.net, 2004-09-24, with a link to http://www.4mbwickedweb.com/sites/melissa/ (since expired);

Another: a Fark thread posting, 2005-01-28, scroll down to the posting of '2005-01-28 10:42:28 AM' by 'XavierCrutch', linking to http://www.stepstonehost.com/jesshomepage/ (since expired);

Another: this weblog post, scroll down to March 13, 2005, 'Personal ads and the great porn conspiracy', where the poster is snared, via IM with AIM user natkat224 this time, and is sent another link to a site using http://adultbureau.sweetheartsconnection.com/ to collect the $40 fee;

Another: another weblog post, 2005-10-28.

A google search for the AIM username 'natkat224' reveals plenty more hits.

So here's a list of the sites found from those links, and via google, so far:

The common host, at all stages, is 'SWEETHEARTSCONNECTION.COM', registered to

INTERTRANS TRADING OVERSEAS LIMITED
VASILEOS OTHONOS 21, FANEROMENIX COMPLEX, OFFICE 102, 6030 LARNACA
N/A
N/A, CA N/A
CY

lots more detail here. SweetheartsConnection.com has terms and conditions that appear to prohibit spamming -- but it turns out that they themselves have a pretty scary entry at RipoffReport.com, anyway, noting:

If you want a free LIFE TIME PASSWORD with Adult Bureau.. you have to apply for a 1 month membership @$39.95 to Sweetheartsconnection.com A DATING SERIVCE ..... charge appears as IT INTERNET SERVICES.

No matter if you request cancellation of service this company will continue to bill you " it gets better " then send you to there home made collection company " Secure debt collections, " two companies in one both fraud

Phony Notices will be sent to the home demanding final payment of a service NEVER USED. They will contact you, try intimidate you into paying a Balance of $200.00 (Sweetheartsconnecton.com automatically rebills your credit card every month @$39.95.

eek.

This weblog post, of 2005-10-28. is shaping up to be the canonical support group for victims of this scam; worth reading the comments there.

Quite a scam, and interesting to note the "personal touch" via email and IM.

adultbureau dating myspace phish scams sweetheartsconnection.com

What Works in Software Development

I already posted this to the link-blog yesterday, but it's so good it's worth promoting more widely. If you write software for a living, you really ought to read the slides for Michael Schwern's excellent 'What Works In Software Development' talk.

It's a long presentation (108 slides!), but during the course of that, he covers:

  • effective teamwork
  • dealing with bad customers
  • dealing with bad management
  • classic coding mistakes
  • classic project management mistakes
  • classic design mistakes
  • test-driven development
  • refactoring
  • patterns

It's a really good synthesis of what I think are the best bits of good OO design, XP, CPAN and perl's design and coding styles, without most of the cruft. I'll be pointing people at this for years to come, I think...

(Found via yoz.)

coding michael-schwern perl presentations software software-development talks work

Planet Antispam: Beta No More

Planet Antispam has been working pretty nicely for the last couple of weeks -- can't say I've noticed any trouble, and its RSS feed is turning out to be a nice aggregation of anti-spam news. On top of that, John Levine was kind enough to set up a CNAME for it at a more appropriate URL -- http://planet.spam.abuse.net/.

As a result, it's now fully-fledged, and fit to lose the 'beta' qualifier. Please bookmark, subscribe to the feeds, and pass on the URL to others you think may be interested!

anti-spam blogging community planet planet-antispam weblogs

Moving Home -- De-Cluttering

I'm moving home.

The flights are booked -- Feb 14th, Valentine's Day, I'll be leaving Orange County and heading back to Dublin permanently. In the meantime, I've been selling stuff, throwing stuff out, decommissioning servers, and making backups.

The server

My erstwhile desktop, later my trusty back-room server, 'jalapeno', was sold earlier today. Thankfully, I bought a 250GB hard drive recently, so I actually had the room to back up its 70GB somewhere beforehand.

Being security-conscious, I overwrote its partitions using pseudo-random data before passing it on ('dd if=/dev/urandom of=/dev/hda9 bs=1024k'). However, being lazy, I did this while the machine was up and running, over an SSH link.

Watching as 'df' produced gibberish output, and as later commands started producing nothing but bus errors, was odd -- a very strange feeling to be actively destroying the disk's data like that. Here's hoping the backups worked...

The yard sale

We had one, in the process selling about $1000 worth of IKEA furniture, books, camping equipment, bits of hardware, sports equipment, and a pink xmas tree:

The local bargain hunters starting knocking on the door at 8:15am, despite the sign's posted start time of 9am. Once we did start bringing items out to the front lawn to sell, there were already about 10 people, which quickly swelled to a mob of 20 by 8:45am. They were keen!

By the end of Saturday, we've sold pretty much all the furniture, all of the sports and camping equipment, most of the hardware that isn't total crap, and only 2 of the books. One shopper's explanation: 'she didn't have the time to read books'.

Still, the yard sale has netted $345. Not bad, and a good feeling to de-clutter so successfully.

backups moving orange-county yard-sales

Music, and iPod Shuffle

I've realised I like the endings of songs; whether I like a song or not, entirely depends on how it ends.

Apple's iPod shuffle algorithm is incredible. I've been spending quite a bit of time listening to it, and I'm sure it's not random; I think it's picking next tracks based partly on the similarity of metadata between the current and candidate tracks, which is quite neat as an automated mixing technique.

So is it random? Google says:

  • yes
  • no; a commenter on that article notes the same thing I'm talking about
  • yes
  • no; can't say I've noticed the Beatles getting a push on mine
  • yes
  • and finally, no answer here, but a pretty cool stats experiment

apple ipod mp3 music randomness shuffle

Google DRM and WON Authentication

So, Google have invented their own DRM, apparently. I'm keen to find out more details; Techdirt and Plasticbag.org are so far the only places I can find in the blogosphere to discuss it in any detail.

One tidbit worth noting from the LA Times coverage:

The Google copy-protection software also imposes a big restriction: The CBS shows, NBA games and other material protected by the software can be watched only on a computer that's connected to the Internet.

"I think it's going to be a problem," said Li, the Forrester analyst, adding that Google executives told her they were trying to fix it.

That's interesting. In my opinion, given that quote, I'll bet Google's DRM is something similar to the copy-protection systems used for many games since about id's Quake 3 and Valve's Half-Life; an online "key server" which validates codes, tracks player IDs, and who's viewing what, "live", as the video is cued up and played.

Some more info on the Half-Life WON authentication system can be found in this GamaSutra article; subscription required -- try viewing this google-cache version with Javascript off if you don't have a sub. That's historical now, of course, since that WON system has been replaced by a new auth protocol as part of Valve's 'Steam' system.

The key factor is the network, separating the dangerous, untrustworthy user machine from the trusted key server. Since the online key server can act as a platform for trusted, known-insubvertable code to run, along with the video server, both being under Google's control, it's actually possible to build reasonably solid DRM on this model. That's as opposed to the usual case, where a reasonably determined teenager can break it in a week of school-nights. ;)

Anyway, that's speculation. It remains to be seen if they've come up with something along the lines of WON authentication -- and if it's still easily subvertable or not.

Update: Aristotle Pagaltzis has a pretty good point in the comments:

Watching video, unlike playing a multiplayer game, is not an activity that inherently requires connecting to a server. Playing a multiplayer game, OTOH, inherently is.

So cracking a multiplayer game's key check is fruitless, because then you can't play online anymore, which was the whole point of the game in the first place. In contrast, a video player with a cracked key check still fulfills its purpose just fine.

I think he's right. That's a key point, demonstrating how WON authentication still can't help -- media playback, as a task, is itself fundamentally crackable.

authentication dont-be-evil drm google google-drm half-life tv video won

Wedding Plans

Myself and the lovely C are planning on getting married, hopefully sometime this year. I've just come across some details about Japanese weddings, and apparently:

'If you are attending a Japanese wedding reception, you are expected to bring cash for a gift (called Oshugi). The amount depends on your relationship with the couple and the region, unless the fixed amount is indicated on the invitation card. The average is 30,000yen ($250) for a friend's wedding. It's important that the cash is enclosed in a special envelope called Shugi-bukuro and your name is written on the front.' ... 'It is a grave insult to give less than $200.'

That gives me a great idea... ;)

funny japan marriage

Planet Antispam

So a few weeks back, I mooted the idea of an anti-spam Planet site, similar to Planet GNOME, Planet Java, Planet Perl et al.

Here's the results: Planet Antispam.

It's still got a few rough edges; notably, the URL is not permanent -- I'd prefer something at a more spam-themed domain -- and the logo is the generic "PlanetPlanet" one. But it's up and running in a beta-ish fashion.

Feel free to bookmark, subscribe, post the URL on, etc.; and if you'd like to give it a better home with an A record at a spam-themed domain, drop me a line.

Update, Jan 17: Thanks to John Levine, it now has a permanent home at http://planet.spam.abuse.net/ . After several weeks of operation, I think it's turning out to be pretty solid, too!

By the way, it also needs more source feeds. If you know of people with blogs, working on/writing about anti-spam (of the email variety), with RSS feeds that work, include the post text, and permit further redistribution of that text, drop us a line and I'll add them.

Finally, here's a picture of a Starbucks SPAM(r) Sandwich. (shudder)

anti-spam blogging community planet planet-antispam weblogs